AI Models & Industry ·
What Did GPT-6 Astra Do With Raw Model Weights? Results
Astra identified games from raw weights, fixed a stuck car by editing 3.5% of a network, and wrote Atari networks from scratch. Here are the numbers and limits.
How engineers use AI, how to do it well, and what it means for your job. Written for people who ship and run the software, not people who build models.
Astra identified games from raw weights, fixed a stuck car by editing 3.5% of a network, and wrote Atari networks from scratch. Here are the numbers and limits.
Tencent's Hy4 was tested on a sketch-to-Blender scene, a multi-agent IPO report with a planted error, and 82-language output. Results and caveats.
Run CCORE's Qwen3.5-4B GLB 3D Coder locally from a GGUF, set the sampling and system prompt, then export Three.js scenes as GLB files for Godot.
Taste Skill 2.1 gives coding agents 20 design directions, public-domain photos and a browser inspector. Here is how to install it and where it falls short.
Cline Pass is a flat monthly plan with 2-5x API rate limits on open models like Kimi K3.1 Pro and GLM 5.3. Models, limit windows, and Cline Desktop features.
Tencent's open-weight world model claims Genie 4-style interactive generation on one consumer GPU, with minute-long keyboard steering. How it compares.
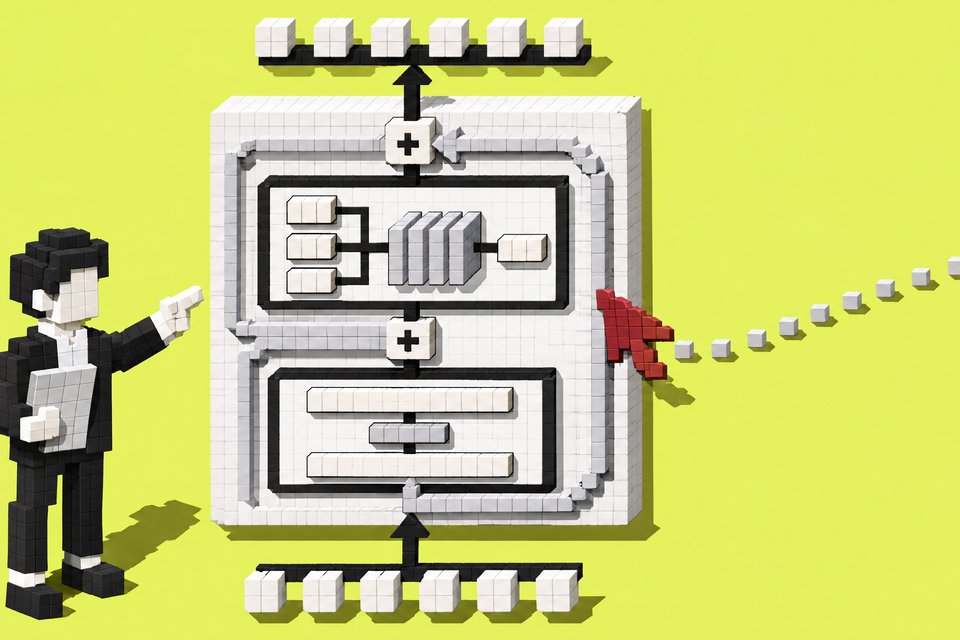
A looped transformer reruns a shared block of layers per token to gain depth without more weights. Here is how NVIDIA's Dory does it, and what it costs.
Learn how one creator set up Codex as a business OS: persistent project context, reusable skills, plugins, sub-agents, schedules and phone voice control.
Run NVIDIA's 3.97B Dory looped model locally: pick a loop count in vLLM, choose per-loop or last-loop KV cache, and pick BF16, MXFP8, NVFP4 or GGUF.
How to decide if you can replace a frontier model with a self-hosted open-weight one: build a swap layer, step down generation by generation, then fine-tune.
Install the 5B MOSS-Image text-to-image model in ComfyUI: where the files go, the node setting that matters, about 28 GB VRAM use and layout mode.
Set up Panda Code agent teams: cheap, balanced and best modes, router-first dispatch, retries, harness failover, model pauses and the S-to-D tier list.
Install Mesh LLM with Docker, start a node with a Gemma model, edit and validate config, and use one OpenAI-compatible API across pooled GPUs.
Anthropic's study found analysts followed their agent's lean 86% of the time. Here are three planning fixes for Claude Code and Codex.
Run SenseNova-Loop-9B-Preview with Transformers 5.18, LightLLM or an SGLang PR build: environment, BF16 loading, thinking mode, MTP and fine-tuning commands.
SenseNova-Loop-9B-Preview reuses 24 layers twice for 56 layer executions from 32 stored layers, with two-stream mHC and 3:1 linear-to-full attention.
Compare personal AI agents Dots, Muse, Duet, Grokbot and Instinct by task: coding, shopping, travel, proactive alerts, plus website access limits.
Hands-on MOSS-Image results: bounding-box layout control, English, Chinese and Urdu text, plus portraits and landscapes from many regions.
Subvocal's radar-based glasses claim to turn silent mouthing into text at 200+ wpm for $499 pre-order. Here is how they work and what remains unproven.
Banks, hotels and schools are deciding how AI agents get in. How signed agents, Visa and Bill, Stripe and Google AP2 shape which sites your agent can use.
How Liquid AI built LFM3-1.7B-Base: 13 gated short convolutions, 5 sliding-window and 6 global attention layers, and a 22T-token recipe to 256K context.
Liquid AI's LFM3-1.7B-Base is a 1.73B model with 256K context that takes about 1 GB at 4-bit. Specs, inference code, thinking toggle and fine-tuning with TRL.
Colibri 2.1 runs large MoE models on one GPU by spreading experts across VRAM, RAM and disk. See the install flow, GGUF import, expert map and profiling tab.
Artificial Analysis Intelligence Index v5 uses 60% private tests and harder agentic coding. The open-model gap grew from 3 to 12 points. Here is what it means.