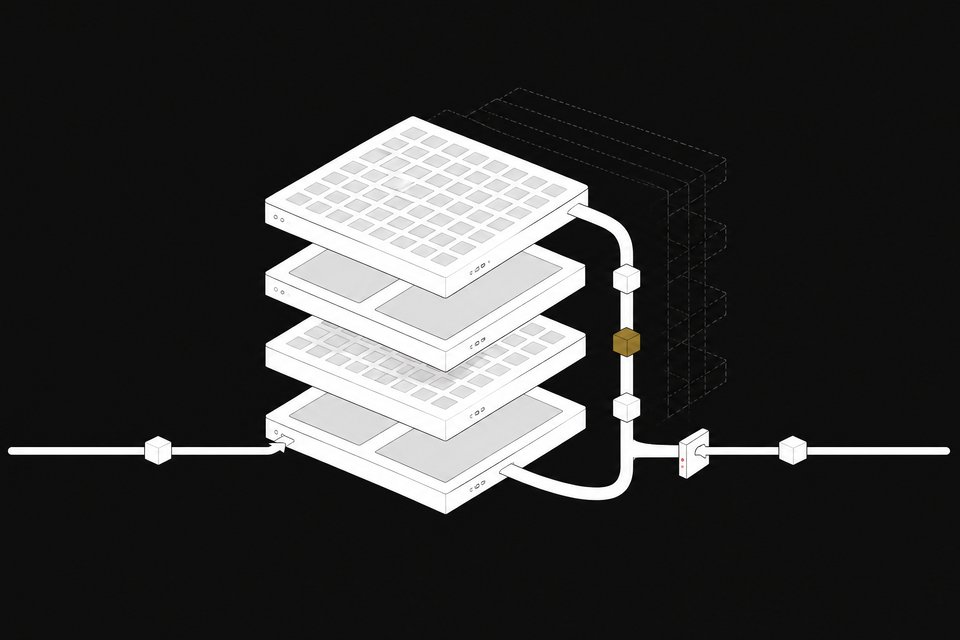
What Is a Looped Transformer? NVIDIA Dory Explained
A looped transformer reruns a shared block of layers per token to gain depth without more weights. Here is how NVIDIA's Dory does it, and what it costs.
A looped transformer reruns a shared block of layers per token to gain depth without more weights. Here is how NVIDIA's Dory does it, and what it costs.
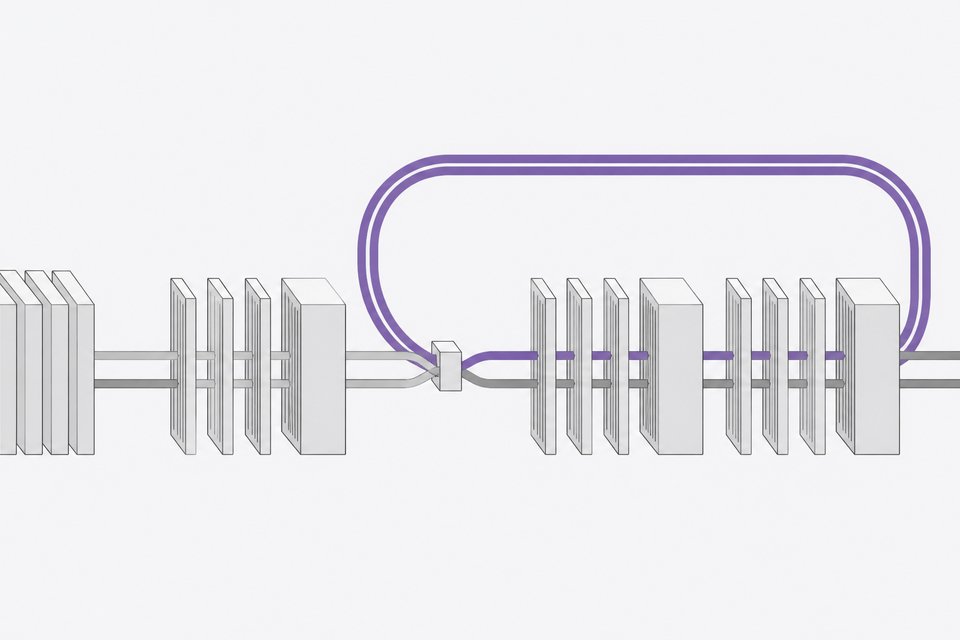
SenseNova-Loop-9B-Preview reuses 24 layers twice for 56 layer executions from 32 stored layers, with two-stream mHC and 3:1 linear-to-full attention.
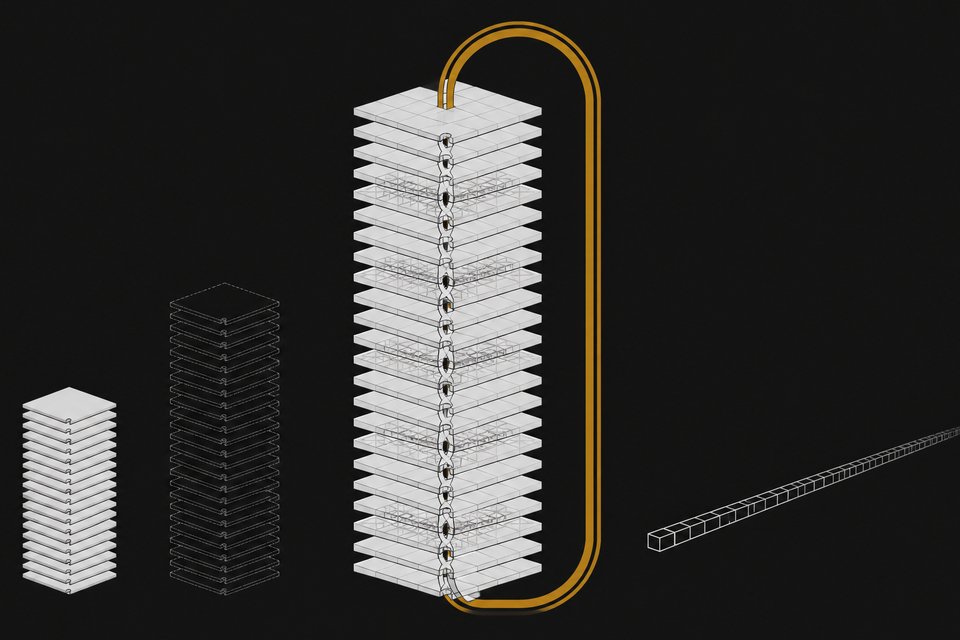
SenseNova-Loop-9B-Preview reuses 24 layers twice with two-stream mHC and 3:1 hybrid attention: ~9B stored parameters, ~14.6B at inference, 256K context.
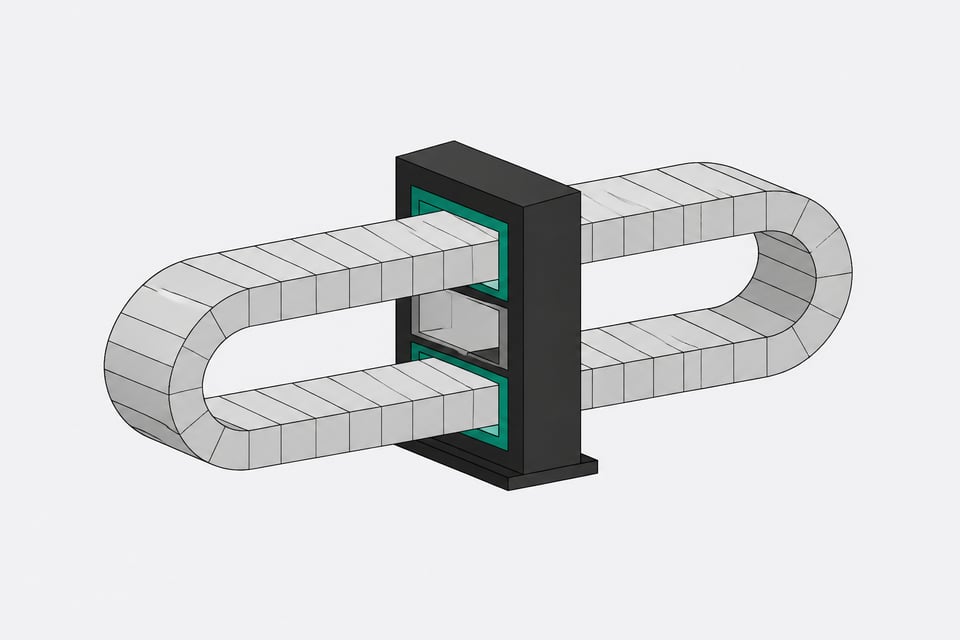
Recurrent depth loops shared transformer layers instead of stacking new ones. Here's how it powers GPT-6 Astra and why it raises governance concerns.