Ripple-65B Tested: How Good Is This Dense Open Model?
Ripple-65B is a 65B dense Apache 2.0 model aimed at agentic coding. See its benchmark wins and gaps, plus a bug-fix, simulation and SQL test.
Find open-weight model benchmarks, hands-on tests and head-to-head scores for newly released open models like Kimi K3.1 Pro, Nemotron and Flint.

Ripple-65B is a 65B dense Apache 2.0 model aimed at agentic coding. See its benchmark wins and gaps, plus a bug-fix, simulation and SQL test.

Tencent's Hy4 was tested on a sketch-to-Blender scene, a multi-agent IPO report with a planted error, and 82-language output. Results and caveats.

Hands-on MOSS-Image results: bounding-box layout control, English, Chinese and Urdu text, plus portraits and landscapes from many regions.

Artificial Analysis Intelligence Index v5 uses 60% private tests and harder agentic coding. The open-model gap grew from 3 to 12 points. Here is what it means.

Phonon 2 averages 5.21% WER on Open ASR leaderboard English sets in 164MB, 15x smaller than Parakeet. See where it holds up and where it fails.

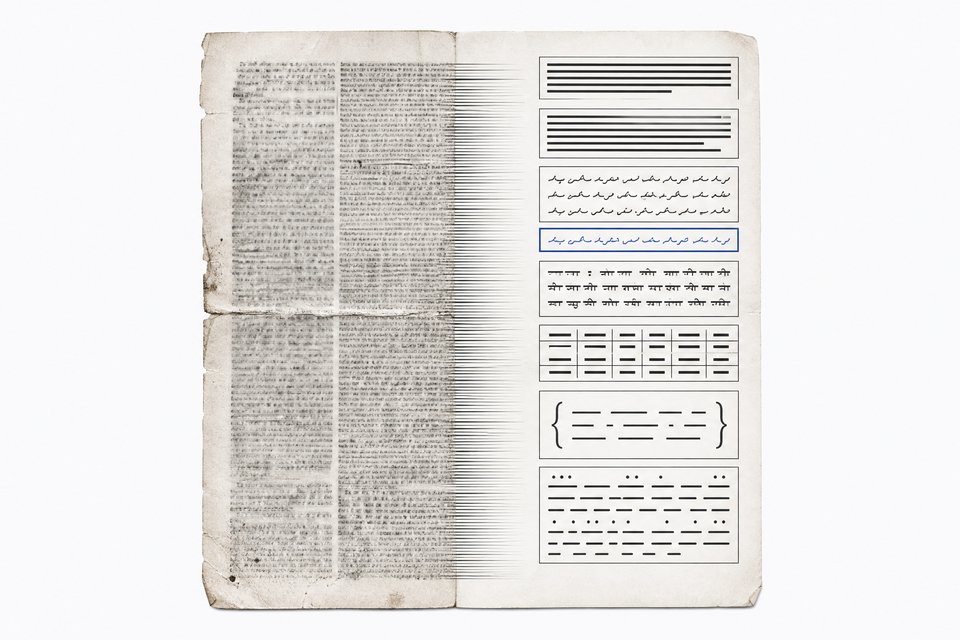
Surya OCR 2.5 tested on invoices, handwriting, an 1883 newspaper, LaTeX, Hindi, Arabic, Urdu and Yoruba. See where it works and where it fails.

Sage A1.5 is a 35B MoE agentic model from Intern. See the reported 38 GB VRAM with llama.cpp, how it was trained, and how it handled sub-agent tasks.

Hands-on test of DiffuSpace's Clover-35B-A3B-Preview diffusion LLM: bug fix, coding, multilingual and logic puzzle results versus its benchmark claims.

LFM3-1.7B is pitched as matching 9B models on agent benchmarks. Here is what the card claims, what hands-on tests showed, and where it fell short.

Unlimited OCR 2 scores about 77 on a 100-page document test while most rivals fall under 30. How SR-SWA attention works, plus where the model still fails.

Nanbeige4.3 33B tops Qwen 3.8 27B and Gemma 4 on most charts, but looped endlessly in a bug-fix and an HTML test. Here is how the claims hold up.

Moss Image is a 5B open-weight text-to-image model under Apache 2.0. See its text rendering, layout control, benchmark claims, and where it falls short.

Kimi K3.1 Pro ranks fourth on Artificial Analysis and sits under a point behind Opus 5.5 on a coding benchmark. Here is what that means for builders.

Hands-on results for NVIDIA's Nemotron-3.5 Bolt E4B: a bug-hunt agent task that failed, a broken HTML scene, and passes on a riddle, physics math and rostering.

Nanbeige4.3-33B leads 17 of 20 benchmarks against Qwen3.8-27B, Gemma4-31B and Muse-Glimmer-30B. See the full table and where it loses.

A 13-task test of Kimi K3.1 Pro against Claude Opus 5.5 in the same Claude Code harness: where Kimi matches Opus, where it cuts corners, and what to check.

Kimi K3.1 Pro tested against Opus 5.5 and GPT 6.1 Soul: pricing, open-weight caveats, and hands-on demos from a Rubik's cube to a Fall Guys clone.

Kimi K3.1 Pro claims near-Opus results, but a six-task KingBench run scored it 5.37/10. See task scores, cost, and how it compares to rivals.

Flint is roughly 10x faster than dense Qwen 3.8 27B but scores 55 vs 73 on Terminal Bench. Here is where each local coding model fits.

InclusionAI's MIT-licensed Ling-3.0 Flash Santé is a 124B MoE healthcare model. See clinical test results, benchmark standing, and its lack of vision.

Carbon-X, a 14.8B DNA model, averages 66.7% on five benchmarks versus 67.5% for GPT-6.1 Sol at far lower cost. Results, weak spots, and limits.

Flint 40B scores 54.9% on Terminal-Bench 2.1 and 74.2% on SWE-bench Verified. See M4 Pro speed, NVFP4 vs BF16, and where Qwen 3.8 still wins.

Sage-A1.5, a 35B MoE agentic model, hits 95.1 on GAIA and 61.2 on SWE-bench Pro. Here is where it beats or trails Kimi-K3, GLM-5.3 and GPT-5.6-sol.

Hands-on look at Vast-10M, which swaps attention in DeepSeek V4 and GLM 5.2 for VSA. Results from a game build, HTML art, a legal corpus and 81 languages.