AI Models & Industry ·
What Did METR's Anthropic Audit Find About Self-Improvement?
METR's audit of Anthropic and an amended S-1 point to AI-led research rising from 1% to 26%, a 1.9x speedup estimate, and heavy redactions.
How executives use AI, how to do it well, and what it means for your job. Written for people who set the direction, not people who build models.
METR's audit of Anthropic and an amended S-1 point to AI-led research rising from 1% to 26%, a 1.9x speedup estimate, and heavy redactions.
AREX-2 is BAAI's 27B open-weights model trained to try, check and revise for hours. See its MLE-Bench Light scores and what it means for harnesses.
Inkling 2 Small is a 594B-parameter, 17B-active multimodal MoE. Hands-on tests in HTML, multilingual output, circuits and vision, plus benchmark standing.
Estimate your monthly SaaS waste from seat counts, 30-day active users, and overlapping tools, with a worked example and a check on which stats to trust.
Five patterns for AI-built websites that convert: the mirror test, one accent color, layered depth, purposeful motion and free-sample tools.
Local votes blocked data centers while AI use climbs. Here is how that hits neo clouds, big tech, offshore siting, overbuild risk and orbital compute.
DSpine is Tencent's roughly 2B draft model for Qwen3.8-27B. See how it speeds up speculative decoding and how it differs from DFlash2 and Eagle 3.
Managed databases cost a markup but save engineering hours. See what the monthly bill really includes and run a simple break-even test on your own numbers.
Clover from Diffuse Space AI is a 35B diffusion language model with 3B active parameters. See how it works and how it fared against Qwen 3.6 Flash.
Traction raised a Series D at a $1.4B valuation with over $100M ARR. Here is how its sensors and AI predict failures in industrial machines.
How Traction won industrial buyers: 88 site visits in year one, an SDR as first hire, up-front risk assessments and 2,500 on-sites a year.
AI agents can clone Excel for about $10 in tokens. Here is how the build-versus-subscribe math compares, and where DIY software still falls short.
Croton Alpha is a free-to-try stealth model with 1M-token context for subagents. See what is known and how it did on coding, vision and translation tests.
MIT's Sparks of Weight Space Programming paper has GPT-6 Astra read and edit another model's weights, lifting a small Qwen's math from 7.9% to 48.1%.
Meta's Muse hit 10 million setups in six weeks. Here is who built it, how a team under 200 did it, the polish details, and the cost-to-serve questions.
Tencent Hy4 adds vision and computer use over the text-only preview, reports a 75.2 Apex Agents score, and is API only for now. Weights are promised.
Ripple-65B is a dense 80-layer transformer where all 65B parameters run per token. How it differs from MoE, plus its attention tweaks and training.
A ranking of 13 AI businesses, from AI SaaS and faceless channels to consulting, scored on technical skill, market demand and durability.
Astra identified games from raw weights, fixed a stuck car by editing 3.5% of a network, and wrote Atari networks from scratch. Here are the numbers and limits.
Tencent's open-weight world model claims Genie 4-style interactive generation on one consumer GPU, with minute-long keyboard steering. How it compares.
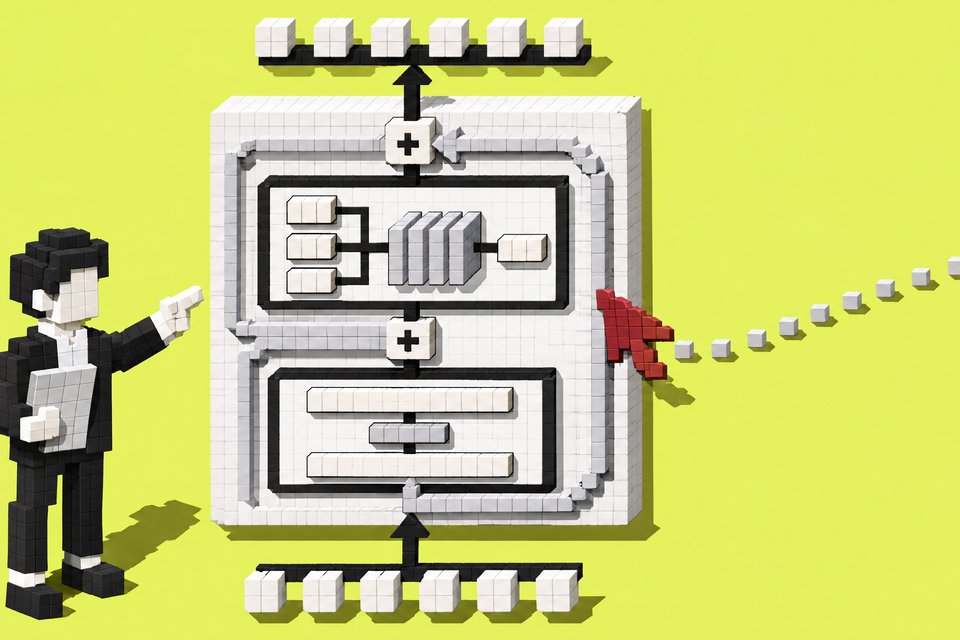
A looped transformer reruns a shared block of layers per token to gain depth without more weights. Here is how NVIDIA's Dory does it, and what it costs.
SenseNova-Loop-9B-Preview reuses 24 layers twice for 56 layer executions from 32 stored layers, with two-stream mHC and 3:1 linear-to-full attention.
Subvocal's radar-based glasses claim to turn silent mouthing into text at 200+ wpm for $499 pre-order. Here is how they work and what remains unproven.
Banks, hotels and schools are deciding how AI agents get in. How signed agents, Visa and Bill, Stripe and Google AP2 shape which sites your agent can use.