What Are Jev-Class Models? The Fast, Cheap Alternative to LLMs for Internal Tools
Jev-class models skip text generation entirely. They return typed choices, scores, and yes/no probabilities instead, which makes them dramatically faster and cheaper for the classification and routing work most internal tools actually do.

- 01Jev-class models skip text generation, instead returning predefined choices, scores, or probabilities.
- 02Decision models eliminate structured-output errors by architecturally restricting answers to a predefined schema.
- 03Jev cuts input costs to roughly $0.042 per million tokens by removing the autoregressive decoding loop.
- 04Open-weight alternatives like OpenJevPro prove the decision-model pattern can run locally with equal accuracy.
- 05Used as a triage gate, decision models can drastically reduce calls to more expensive, frontier LLMs.
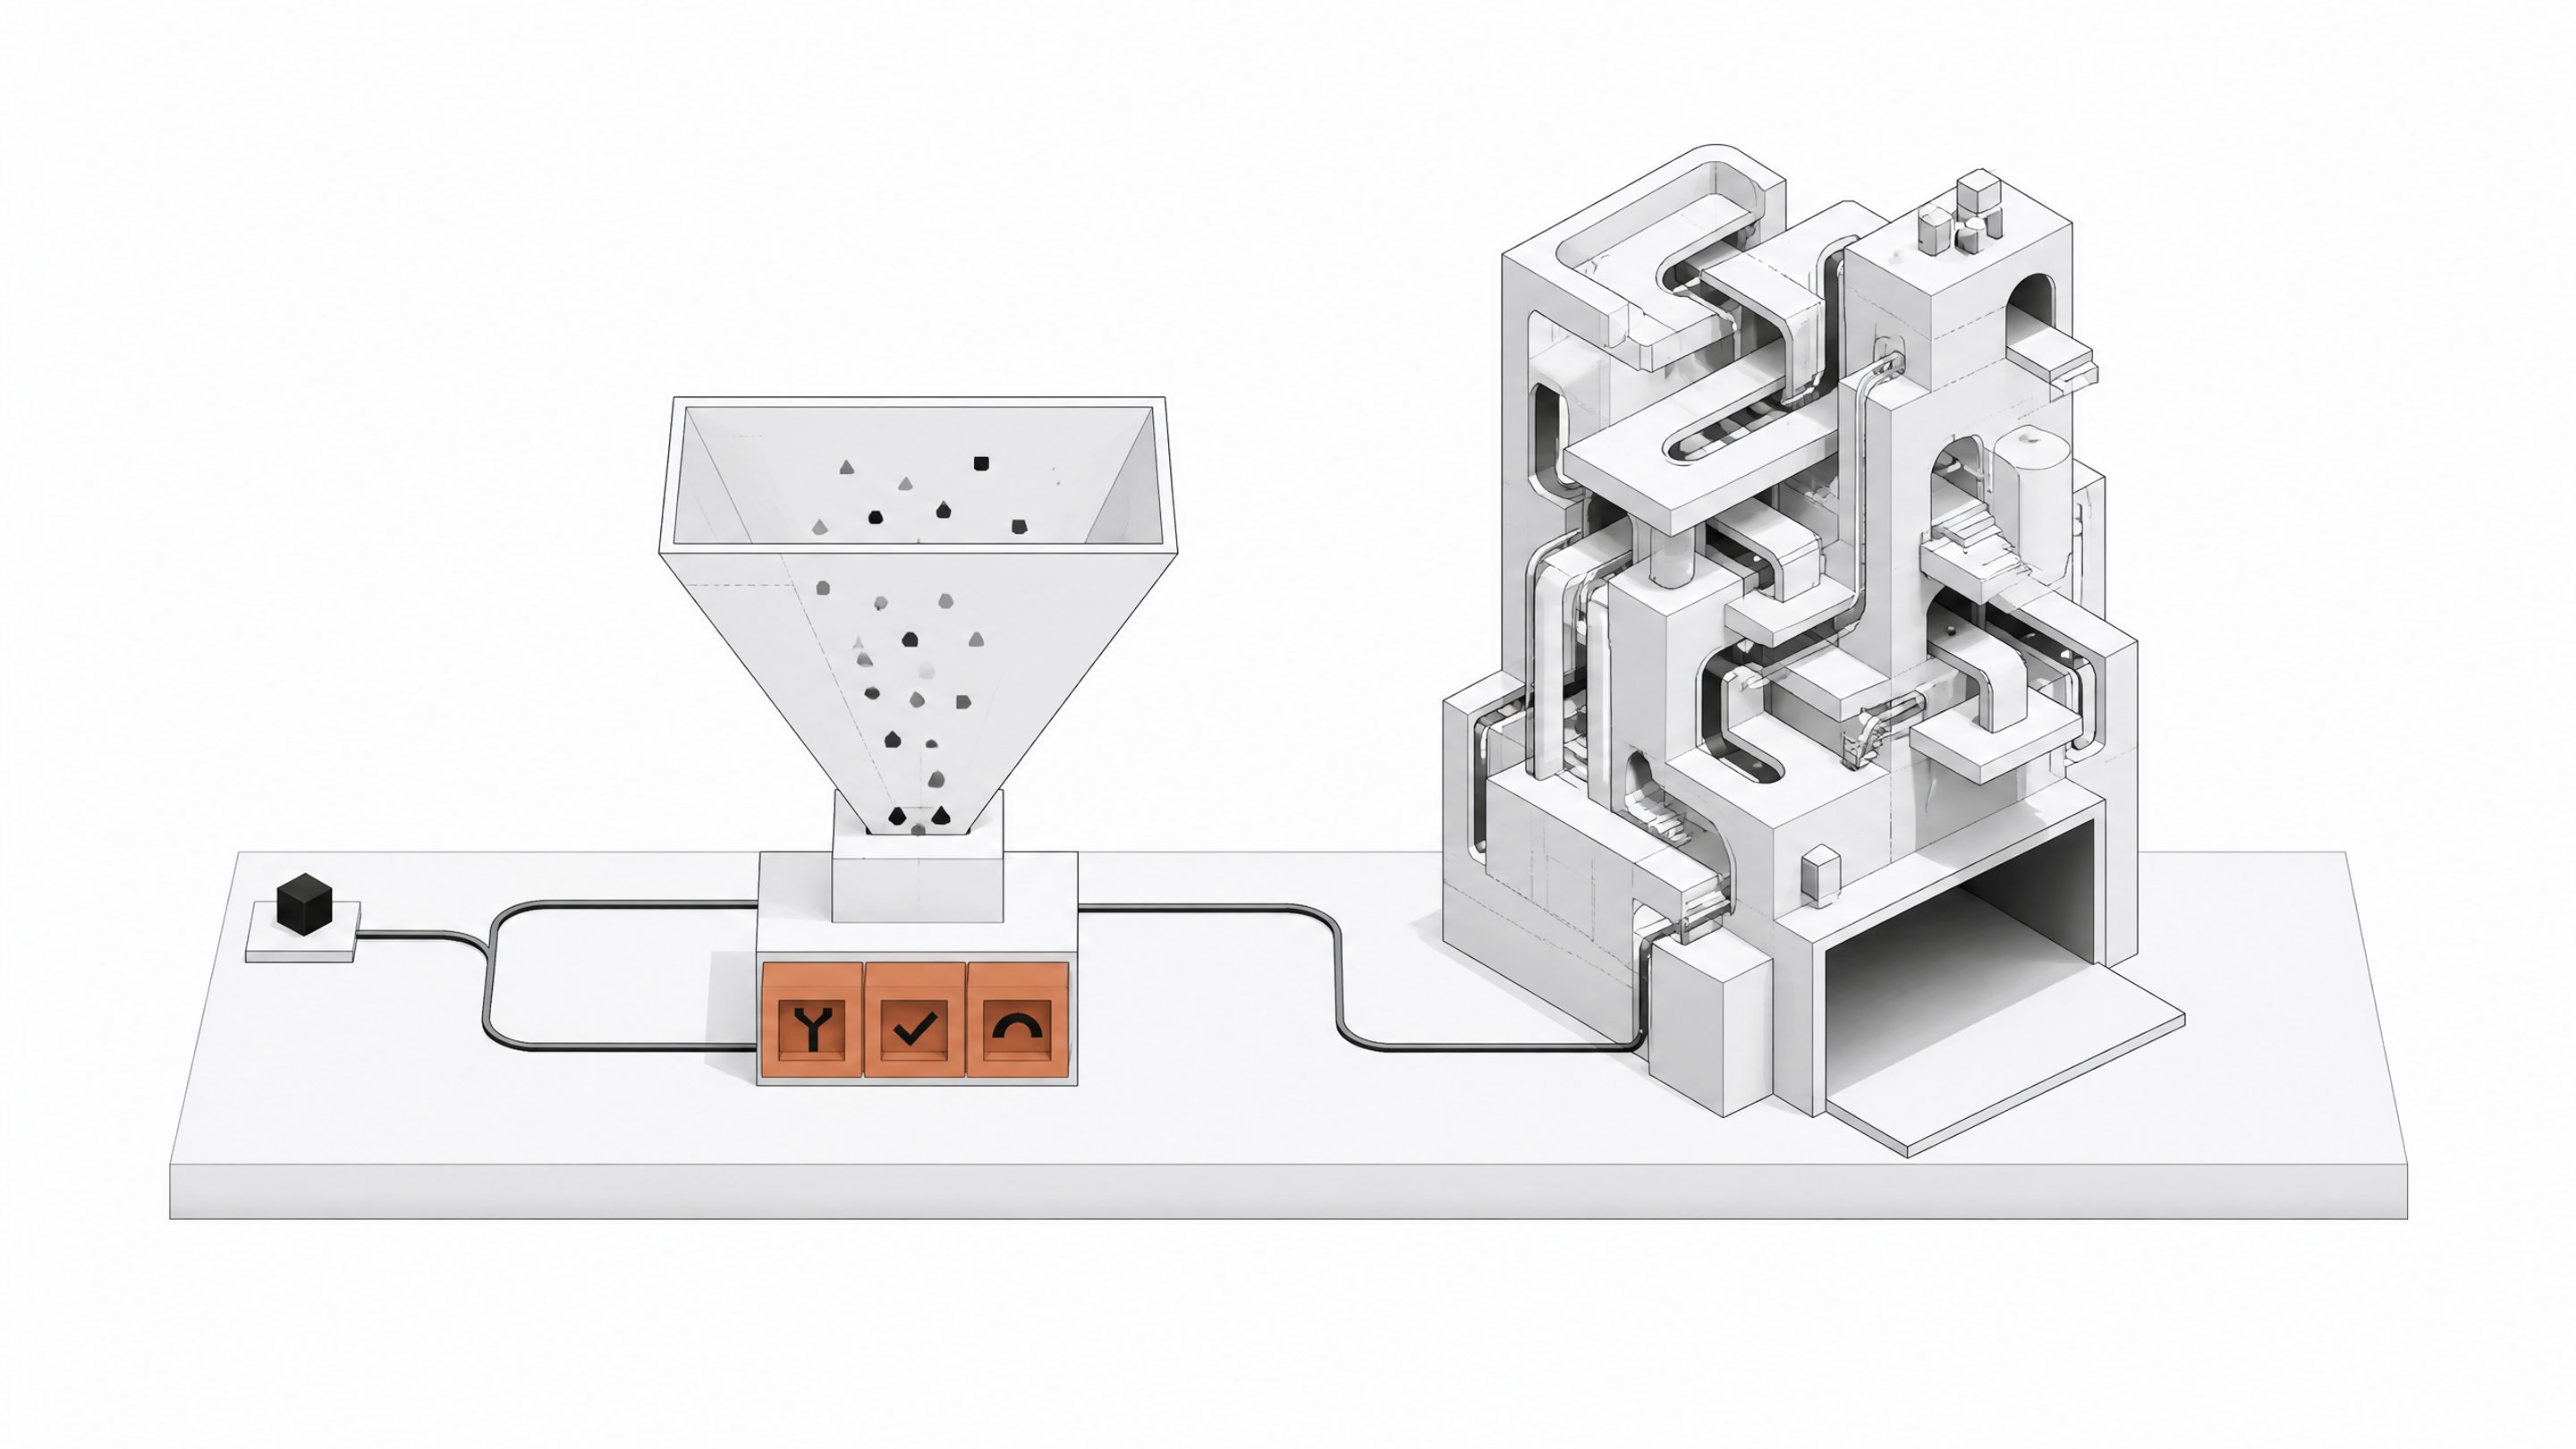
Jev models are a class of AI model that TypeSafe AI calls "System One Models," or decision models. Instead of generating text one token at a time, a Jev model takes in some state plus a typed question and returns a bounded answer: a choice from a fixed list, a score against a rubric, or a yes/no probability. No essay, no chat turn, no free-text output to parse or hallucinate.12
TypeSafe launched Jev on September 15, 2026, founded by Diogo Almeida, a co-inventor of ChatGPT's training methods at OpenAI. The pitch is blunt: most of the AI calls inside real software aren't asking a model to write anything. They're asking it to decide something.13
How is a decision model different from a chat LLM?
A chat-style LLM generates text sequentially: predict the next token, append it, predict again, repeat until done. That's why longer answers take longer and cost more. Every output token gets generated and billed individually.
A decision model works differently. Given a state and a set of typed questions, it evaluates all the possible answers against that state in a single pass, rather than writing its way toward one. The Register described it plainly: "Jev is a classifier with brains. When given a set of data, it returns predefined 'typed' decisions that the developer decided on beforehand, along with probability distributions."4
Jev supports exactly three question types, called primitives:
- Choice. Pick one option from a defined set, with a probability attached to each option.41
- Score. Rate the state against an ordered rubric, such as low/medium/high urgency.15
- Noul. A single yes/no probability, named after the Bernoulli distribution.41
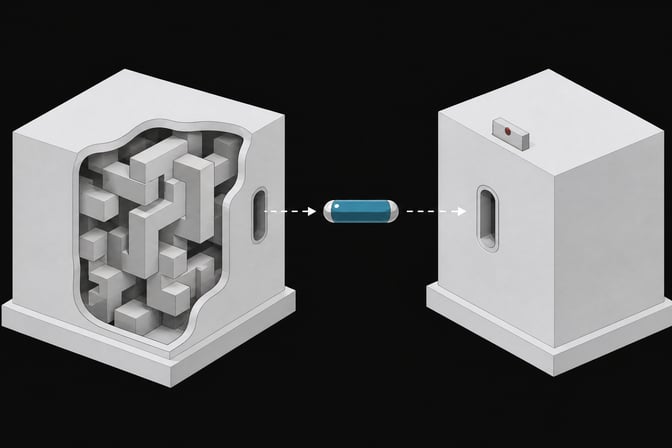
Because every possible answer is defined ahead of time, the model is architecturally incapable of returning something outside that schema. TypeSafe reports a 0% structured-output error rate for Jev, against non-zero error rates for comparable LLMs asked to do the same job, including a 45.5% malformed-output rate for Claude Haiku 4.5 and a 17.0% tool-call error rate for GPT-5.6 Sol on the same benchmark.15 Be precise about what that guarantee covers: Jev can't produce an invalid value, but it can still confidently pick the wrong valid one. As one developer put it after testing it, "it can't answer outside your options, but it can still pick the wrong one, so the probabilities are the really useful part."6
Why do bounded answers make it faster and cheaper?
The economics follow directly from the architecture. No autoregressive decoding loop, and per TypeSafe, no output tokens worth metering, so pricing runs at $0.042 per million input tokens with output free.14 That's roughly 1/48th the input price of a mid-tier frontier model like GPT-5.6 Terra, which runs $2.00 per million input tokens plus $12.00 per million output tokens.1 Simon Willison noted it undercuts even OpenAI's cheapest model, GPT-5 Nano, at $0.05 per million.2
Latency tells the same story. TypeSafe reports end-to-end response times of 70 to 500 milliseconds, against 3 to 329 seconds for frontier LLMs doing comparable work, a claimed 193.6x speed advantage and 444.6x cost advantage on its internal workflow benchmarks.1 DataCamp's independent review lands on similar multiples: 40 to 400x cheaper and 20 to 200x faster than chat-style models for equivalent tasks.5 Vercel engineer Pranit Sharma reported 5 to 18x faster responses with improved accuracy when he swapped Jev in for command-safety classification.7
None of this comes free on accuracy. On TypeSafe's own four-workflow benchmark, Jev hit 67.8% agreement with reference answers, roughly tied with GPT-5.6 Terra (67.9%) but several points behind top performers like GPT-5.6 Sol (74.1%) and Claude Opus 5 (73.1%), while costing about 1/76th as much per case, roughly $0.0004 versus far higher per-case costs for the frontier models.5 The context window is capped at 64,000 tokens, and TypeSafe's own documentation warns that feeding it extraneous context actually lowers accuracy rather than helping.3
What is a Jev model good for, and where does it break?
Decision models are built for a narrow job: bounded classification, routing, and scoring where the set of valid answers is known in advance. That covers a lot of ground inside real internal tools:
- Ticket and email triage. Sorting incoming requests into categories or urgency tiers.
- Tool-call gating. Deciding which function an agent should invoke next, or whether to invoke one at all.
- Guardrails and safety checks. Flagging risky commands or content before they execute.
- Lightweight scoring. Rating leads, spreadsheet rows, or support tickets against a fixed rubric.
TypeSafe's own "model jaggedness" documentation is candid about where jev-1.13 struggles: math and counting, comparing dates and times, multi-hop reasoning that requires indirection, very large or irrelevant context, and adversarial or injected content. TypeSafe recommends handling those cases in code rather than asking the model to do it.8 Independent research backs up the unevenness. A Nanyang Technological University study called REFLEX used Jev as a fast gate in front of a strong LLM fallback and found it hit 98.4% accuracy on straightforward tool selection, but only 52.0% accuracy on the harder judgment call of whether to act at all.9 That's the pattern to plan around: decision models are strong on bounded classification, weaker on open-ended authorization calls that need broader context.
What they're not built for is generation. Writing copy, drafting code, explaining reasoning, or holding a multi-turn conversation are still frontier-LLM jobs. A Reddit test that pitted Jev against GPT-5.4 nano on a simple ticket-classification task found it gave the same answer, ran a bit faster, and cost about half as much, but the author was careful to flag that as one informal run, not a benchmark.6 Forbes reported a similar mixed picture: one developer found Jev classified business emails at a fraction of Gemini's cost, but Gemini was slightly more accurate on the same task.7 The lesson is consistent across every source: the cost and speed win is real, but accuracy is task-dependent, and you should test on your own data before betting a workflow on it.
Why would a company self-host this instead of renting it?
Jev itself is a hosted, proprietary API, and TypeSafe hasn't released the weights. That's the catch for teams that like the pattern but not the vendor lock-in. What has leaked out fast is the pattern itself, and open-weight teams didn't wait for permission to copy it. Within days of launch, several open reimplementations of the typed-decision approach showed up, running on open-weight backbones instead of TypeSafe's servers:
- Laya, a 421M-parameter model built on ModernBERT.10
- SemIf / OpenJev, built on a Qwen3.5 backbone.10
- Kev-0.5B, a small footprint alternative.10
- OpenJevPro, a harness built for production use on open-weight LLMs.10
One of those, OpenJevPro, reported 100% in-domain decision agreement with TypeSafe's Jev on a 30-query Banking77-based benchmark while running faster end to end, about 508 milliseconds against Jev's 777 milliseconds, on cloud-accelerated open-weight backends.10 That's the important signal here: the speed and cost advantage comes from the shape of the problem, state plus typed question in, calibrated probability out, not from any secret sauce unique to TypeSafe's servers. A team with a Qwen3 or DeepSeek model already running through an inference engine like vLLM can build the same decision layer on hardware it owns.
That matters because this is exactly the kind of software layer worth owning rather than renting. A routing or triage decision that fires thousands of times a day, priced per call through someone else's API, adds up in ways a fixed-cost self-hosted model doesn't. The real crossover math on self-hosting versus API pricing usually favors ownership once call volume gets high enough, and decision models, cheap per call but run constantly, are close to the ideal case for that math.
Does the evidence actually hold up?
The strongest independent validation so far comes from that same REFLEX study. Using Jev as a decision gate ahead of a strong-model fallback, researchers hit 95% task success while cutting strong-model calls by 72.7% on a controlled 100-task benchmark, and that reduction held across three different fallback model families.9 Vercel reported Jev was adopted faster than any model in its AI Gateway's history, reaching about 13% of paid teams within 24 hours of launch, roughly twice the adoption rate of the GPT-5.6 family. A practitioner writing about production use summarized the shift bluntly: understanding a user's intent is a classification problem, and "classification is exactly what a decision model is for."11
Where this fits in an internal-tools stack
The practical takeaway isn't that decision models replace chat LLMs. It's that most agent loops and internal tools are doing far more deciding than writing, and paying frontier-chatbot prices for every one of those decisions is wasteful. The pattern that's emerging looks like a control layer of cheap, fast typed decisions, whether that's Jev itself or an open-weight equivalent running on your own hardware, sitting in front of a frontier model reserved for the small number of steps that genuinely need generation or reasoning.
There's a governance wrinkle worth naming, too. Because the pattern is so cheap and simple to stand up, individual teams can wire a decision layer into a Slack bot or internal script without IT ever seeing it, which is exactly the kind of shadow AI sprawl that's easy to lose track of once it's running in a dozen places at once. Treat the decision layer like any other piece of infrastructure you'd want an inventory of, not a side project someone quietly built over a weekend.
It can't return an answer outside the options you define, so TypeSafe reports a 0% structured-output error rate. But it can still confidently pick the wrong valid option, so accuracy and calibration still need checking, especially since it's several points behind top frontier models on TypeSafe's own benchmark.156
No. Because the pattern (state plus typed question, probability out) is simple, open-weight reimplementations like Laya, SemIf, Kev, and OpenJevPro let teams run the same approach on self-hosted open-weight models instead of paying per call for TypeSafe's proprietary API.10
TypeSafe's own documentation flags math and counting, date comparisons, multi-hop reasoning, and adversarial content as weak spots, and independent research found accuracy drops sharply on judgment calls like deciding whether to act at all, versus simple classification. Handle those in code or route them to a full LLM instead.89
- 1Introducing System One Models & JevTypeSafe AI (company blog)
- 2Jev introduces a new shape of LLM—System One, aka Decision ModelsSimon Willison's Weblog
- 3TypeSafe AI's Jev offers an alternative to LLMs that claims to be 193x faster and 445x cheaperTom's Hardware
- 4Shut up and calculate: Jev's new AI primitives for codersThe Register
- 5Jev: TypeSafe's System One Model That Never HallucinatesDataCamp
- 6Tried Jev, a model that returns typed decisions instead of text. Notes + Python guideReddit r/LLMDevs
- 7Why Everyone Is Talking About Jev, The AI That Doesn't ChatForbes
- 8Jev 1.13 jaggednessTypeSafe AI (official docs)
- 9REFLEX with Jev for Efficient Selective Control in LLM AgentsarXiv (Nanyang Technological University)
- 10OpenJevPro: Production-Grade Open Alternative to TypeSafe JevGitHub (zhangcy122/OpenJev)
- 11Decision models like Jev are a genuinely different shape of thingLinkedIn (Francois Lopitaux, practitioner post)