How to Build a Competitor Tracker App with the You.com API
Build a competitor or market tracker with You.com's live web search API instead of paying $15K-$150K a year for Crayon, Klue, or Meltwater.

How do you build a competitor tracker app with the You.com API?
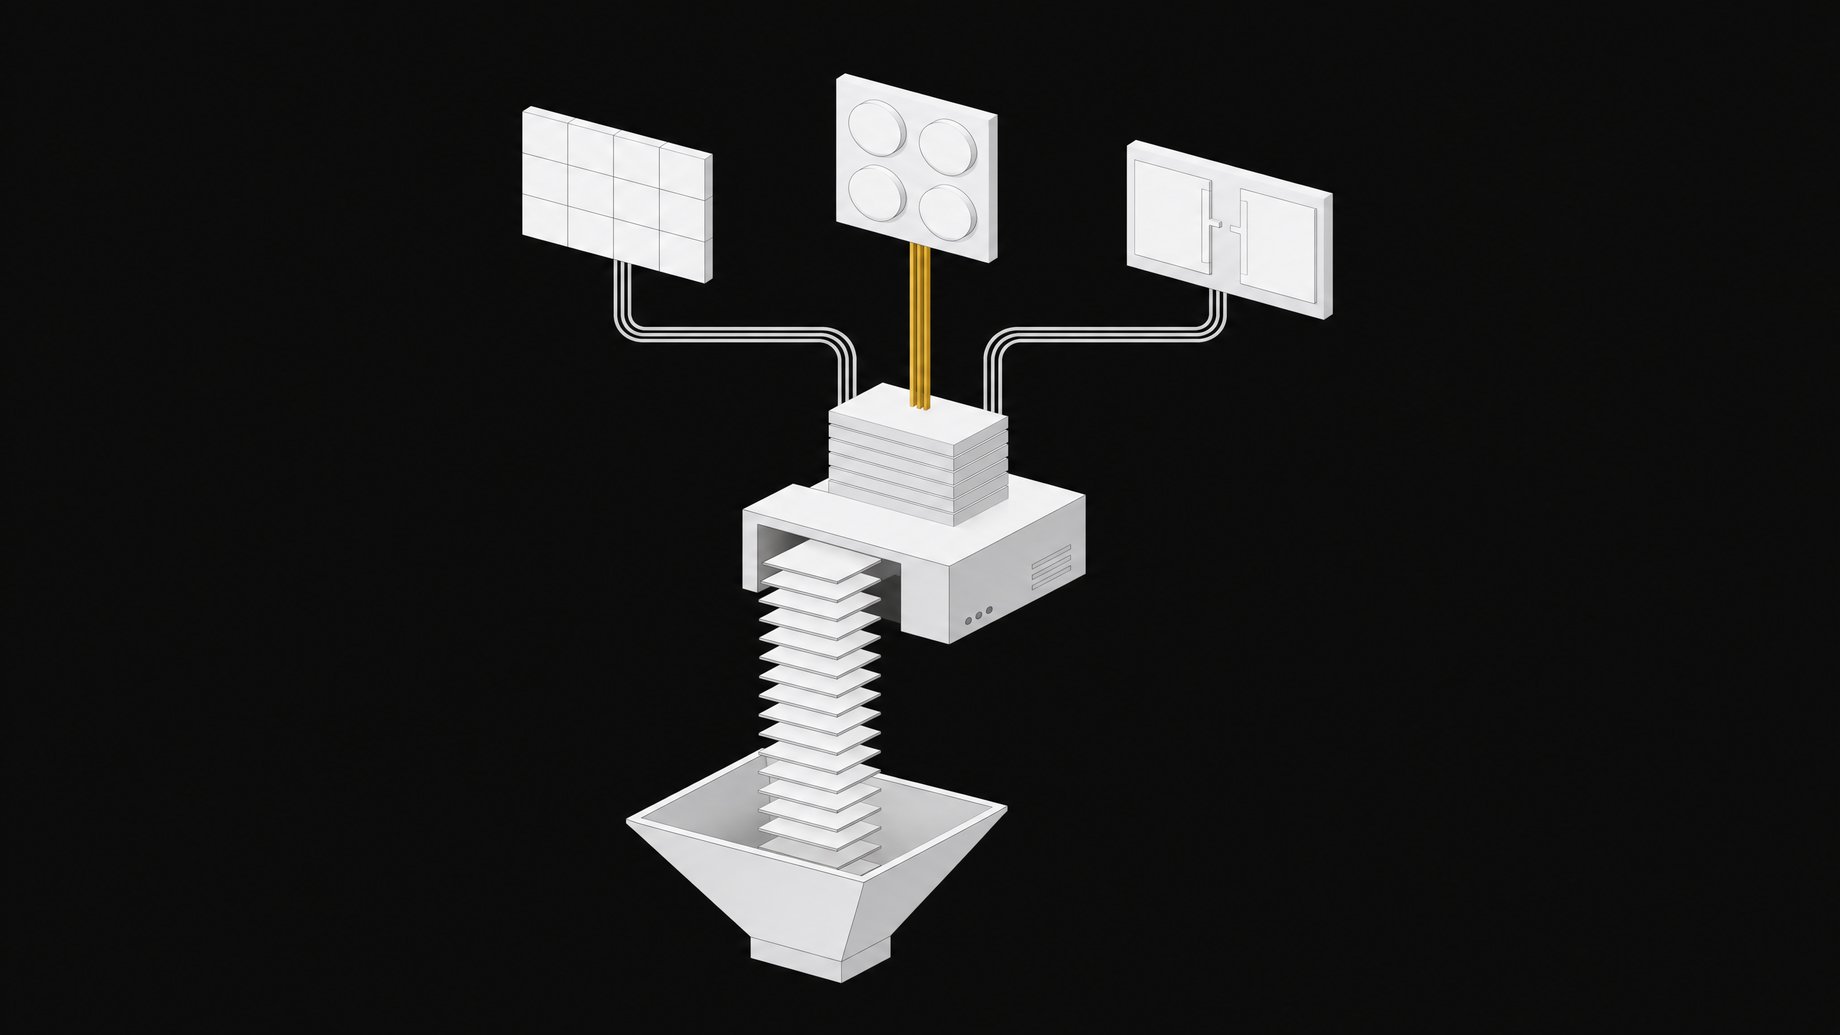
Pair a live-web data API like You.com with a full-stack app compiler. The API handles retrieval and extraction, so you're not scraping anything yourself. The compiler turns your spec into a deployed app with a database, auth, and a schedule, so you're not hand-building infrastructure either. Most teams go from idea to a working competitor tracker or market monitor in a few hours, for roughly $100 to $200 in build cost, instead of signing a $15,000-to-$150,000-a-year contract with Crayon, Klue, or Meltwater.
That's the whole pitch. The rest of this is how it actually works, and where it doesn't.
TL;DR
- Enterprise tools like Crayon, Klue, and Meltwater charge $15,000 to $150,000 a year for competitive and market monitoring.
- Pairing a live web search API with an app compiler gives you the data, database, auth, and schedule for roughly $100 to $200 in build cost.
- Homegrown scraping pipelines tend to break when target sites redesign, and maintaining one commonly runs $100 to $1,500 or more a month.
- A base LLM can't answer "what did my competitor ship last week" because of its training cutoff, so you need a retrieval layer feeding it current pages.
- A deployed, owned app is easier to audit and govern than the shadow AI behind 43% of AI-related security incidents.
- Buying still makes sense for large sales-org battlecard distribution, strict compliance needs, massive scale, or when nobody wants to own the tool.
Why doesn't 'just use ChatGPT' work here?
Ask ChatGPT what your competitor shipped last week and it either says it doesn't know or confidently guesses. Base LLMs have a training cutoff. Without a retrieval layer feeding them current pages, they're reasoning from stale data and filling the gaps with plausible-sounding fiction.
The other instinct is to build it yourself: a cron job, a scraper, a spreadsheet, the same impulse behind the shift toward framework-free RAG pipelines built in plain code instead of rented from a framework. It works for about three weeks. Then the target site redesigns its pricing page, your CSS selectors stop matching, and the pipeline silently returns nothing. Practitioners describe this exact failure mode constantly: JavaScript-heavy sites that load content late, layout changes that break parsing, bot detection that blocks the request entirely. Scraper maintenance for a single working pipeline commonly runs $100 to $1,500 or more a month in developer time, and that's before anyone looks at the data it's producing.
So you need two things a basic script and a vanilla LLM can't give you: a reliable way to pull current web content, and somewhere durable to put the output.
What does real-time web intelligence actually require?
Strip away the marketing language and a real intelligence tool, whether it tracks a competitor's pricing, a market's sentiment, or a set of news feeds, needs four components:
- Live web and news retrieval. A way to ask "what's new about X" and get back current, structured results, not a six-month-old index.
- Page-content extraction. Search results alone are metadata and snippets. You need the actual page text, cleanly converted from HTML, to feed an LLM anything useful.
- Synthesis with citations. Raw pages aren't a brief. Something needs to read across sources, pull out what changed, and attach sources so a human can verify it.
- A persistent app. Database, authentication, a scheduler to run the check daily, and a UI someone will actually open. This is the part most DIY projects skip and most SaaS tools exist specifically to provide.
This is why companies default to buying a platform. Building all four from scratch is a real engineering project. But you don't need to build all four from scratch. You need to wire two things together.
Why use You.com as an API rather than a search box for the data layer?
You.com's Web Search API is built for this: live web and news results returned as structured, LLM-ready data instead of a page of blue links, with p50 latency around 0.4 seconds. It costs $5 per 1,000 calls, with full-page content extraction available as an add-on at $1 per 1,000 pages. New accounts get $100 in free credit, which covers roughly 20,000 searches before you spend a dollar.
That covers components one and two. For synthesis, You.com's Research API plans multi-step queries, cross-references sources, and returns cited answers, priced in tiers from $12 per 1,000 calls at the Lite tier up to $1,200 per 1,000 at the Frontier tier depending on depth and latency needed. For a daily competitor check, you'll almost always want Lite or a mid tier, not Frontier.
You don't even have to assemble the research-plus-extraction logic yourself. You.com publishes a ready-made Competitive Intel Agent Skill that chains its research and contents tools into a standing brief covering positioning, traction, pricing, and recent moves, fully sourced. It's a template for exactly the use case this piece is about.
This isn't a hypothetical pattern, either. Databricks and You.com have documented wiring the Search API into agent workflows for retail and e-commerce, specifically for adjusting pricing based on real-time competitor data and tracking market trends, with the API registered as a governed, auditable connection rather than a loose credential in someone's script.
How does the app layer work when you compile a spec instead of coding one?
You.com gets you the data. You still need somewhere for it to live, with a schedule, a login, and a screen.
An app compiler lets you describe what you want in plain language and compiles that spec into a deployed full-stack app with a backend, database, authentication, and frontend.
Build vs. buy: what do the numbers say?
Here's the comparison that matters before you touch either tool.
Entry-level enterprise competitive-intelligence platforms like Crayon and Klue are quote-only, typically landing near $15,000 to $16,000 a year even at the bottom tier, and both assume a dedicated analyst running the tool day to day. Full deployments scale to $25,000-$60,000 a year for Crayon and $30,000-$100,000 for Klue. Media and social monitoring platforms like Meltwater run $15,000 to $150,000-plus annually depending on tier, with 12-month minimum contracts and no self-serve or monthly option. Vendr's purchase data puts the median Meltwater buyer at $25,800 a year, with a range from $5,375 to $56,993 depending on scope.
Against that, a You.com-plus-custom-app stack runs on API usage billed in dollars per thousand calls rather than tens of thousands per year. Even running the tool continuously for a year, you're looking at low hundreds of dollars in API spend for a single-target monitor, not five figures.
The gap isn't marginal. It's an order of magnitude or more, and it's part of a broader pattern: AI agents are already displacing specific categories of software, the same way a self-built voice agent now replaces a call-center seat license. The enterprise price covers things you may not need yet: broad battlecard distribution across a sales floor, pre-built integrations into a dozen other tools, dedicated support. If what you actually need is one reliable, sourced daily brief, you're paying for overhead you won't use.
How do you build a competitor watcher, step by step?
Here's roughly how the build goes in practice:
- Write the spec. Describe the app in plain language: track three competitor domains, pull their pricing and blog pages daily, store historical snapshots, show a dashboard, and email a digest every morning.
- Wire the data call. Add a You.com Research or Contents API call as an integration step, pointed at the competitor domains, requesting the fields you want: pricing text, recent posts, any changed copy.
- Store it. A managed database takes the API response and persists it against your schema automatically. No manual migration needed.
- Schedule it. Set the job to run daily. The platform handles the cron layer; you don't manage a server for it.
- Read the output. The dashboard shows what changed since the last run, with the source links You.com's API returns attached to each item.
That's the whole build. No scraper to maintain, no selector to fix when a competitor redesigns their pricing page, because you're pulling structured content through an API built to handle that.
Where does this fit in the bigger picture?
This kind of project is already happening inside most companies, just without anyone's knowledge. Employees build their own tools with whatever AI access they have, and it mostly works until it doesn't. IBM's 2026 Cost of a Data Breach research found shadow AI involved in 43% of AI-related security incidents, up from 20% the year before. Separately, the average company now runs over 100 SaaS applications, a number that keeps climbing.
A purpose-built intelligence app doesn't automatically solve governance, but it changes the shape of the problem. It's a named, deployed app with a database and an owner, not a script on someone's laptop or an unauthorized subscription nobody remembers approving. It's a repo you can audit, hand to IT, or shut down cleanly. That's the software-ownership argument in practice: the tool exists as an asset your team controls, not a seat you're renting indefinitely or a shadow process nobody can account for.
When does buying still make sense?
DIY isn't always the right call. Reach for an established platform instead when:
- You need battlecards distributed to a large sales org. Crayon and Klue are built for that distribution and adoption problem, not just data collection.
- You're under strict compliance or SLA requirements. Regulated industries often need vendor certifications and guaranteed uptime a self-built tool won't carry out of the box.
- You're monitoring at massive scale. Hundreds of competitors or global media coverage across many markets starts to justify the enterprise price tag.
- Nobody on the team wants to own it. An owned app still needs an owner. If that's not available, a vendor with support staff is the safer bet.
If none of those apply, you're very likely paying enterprise prices for a problem a weekend build can solve.
| Annual Cost | Setup Time | Battlecard Distribution Support | Compliance/SLA Guarantees | You Own the Codebase | |
|---|---|---|---|---|---|
| RecommendedRemy + You.com stackA single, owned, sourced daily brief | $1,200-2,500/yr | Hours | Low | Low | Yes |
| CrayonSales-wide battlecard distribution | $15,000-60,000/yr | Weeks | High | Medium | No |
| KlueSales enablement at scale | $15,000-100,000/yr | Weeks | High | Medium | No |
| MeltwaterRegulated, large-scale media monitoring | $15,000-150,000/yr | Weeks | Medium | High | No |
What does the stack look like at a glance?
For a single competitor or market-monitoring use case: You.com's Web Search API at $5 per 1,000 calls, Contents extraction at $1 per 1,000 pages, and Research API tiers starting at $12 per 1,000 calls handle the data side. Compare that to $15,000-$100,000 a year for Crayon or Klue, or $15,000-$150,000 for Meltwater, both requiring annual contracts and a dedicated operator. Rent the overhead, or own a small, specific tool that does exactly the one thing you needed.
Frequently Asked Questions
What's the cheapest way to build a real-time competitor tracker?
Pair You.com's Web Search or Contents API, priced from $5 per 1,000 calls, with Remy at $99 a month. Remy's pricing FAQ puts taking a project from idea to a deployed app at $100 to $500 in tokens, far below the $15,000-plus annual contracts enterprise CI tools require.
Do I still need to write scrapers if I use You.com's API?
No. You.com's Web Search and Contents APIs return structured, LLM-ready page content directly, so you skip the HTML parsing, bot-detection workarounds, and selector maintenance that make homemade scrapers break every time a target site changes its layout.
How long does it actually take to build one of these apps?
A typical initial build in Remy, from plain-language spec to a deployed full-stack app, takes about an hour. Wiring in a You.com API call and setting a daily schedule adds a modest amount of time on top, but a working prototype in a single afternoon is realistic.
When should I buy Crayon, Klue, or Meltwater instead of building this myself?
Reach for an established platform when you need to distribute battlecards across a large sales floor, meet strict compliance or SLA requirements, monitor at very large scale, or when nobody on your team can own and maintain a self-built tool.
Is a self-built intelligence app actually more secure than a quick internal script?
It can be, if you treat it as an owned asset rather than an unmanaged shadow tool. Shadow AI tools built without any oversight were involved in 43% of AI-related security incidents in IBM's 2026 breach research, up sharply from the prior year, which is the governance risk a named, auditable app is meant to avoid.
How we source, write, and correct our articles. Editorial standards