Congestion Pricing in API SaaS: Why Your AI Bill Spikes Like Rush-Hour Traffic
AI providers borrowed a pricing trick from toll roads and power grids. Here's what it means when your API bill starts moving like rush-hour traffic.

- 01AI providers use congestion pricing to charge premiums for compute access during peak demand.
- 02Agentic AI could drive a 24-fold increase in global token consumption by 2030.
- 03Despite 98% of organizations tracking AI spend, 73% of AI projects still exceed their budgets.
- 04Self-hosting often becomes cheaper than managed APIs above 100 million tokens per month.
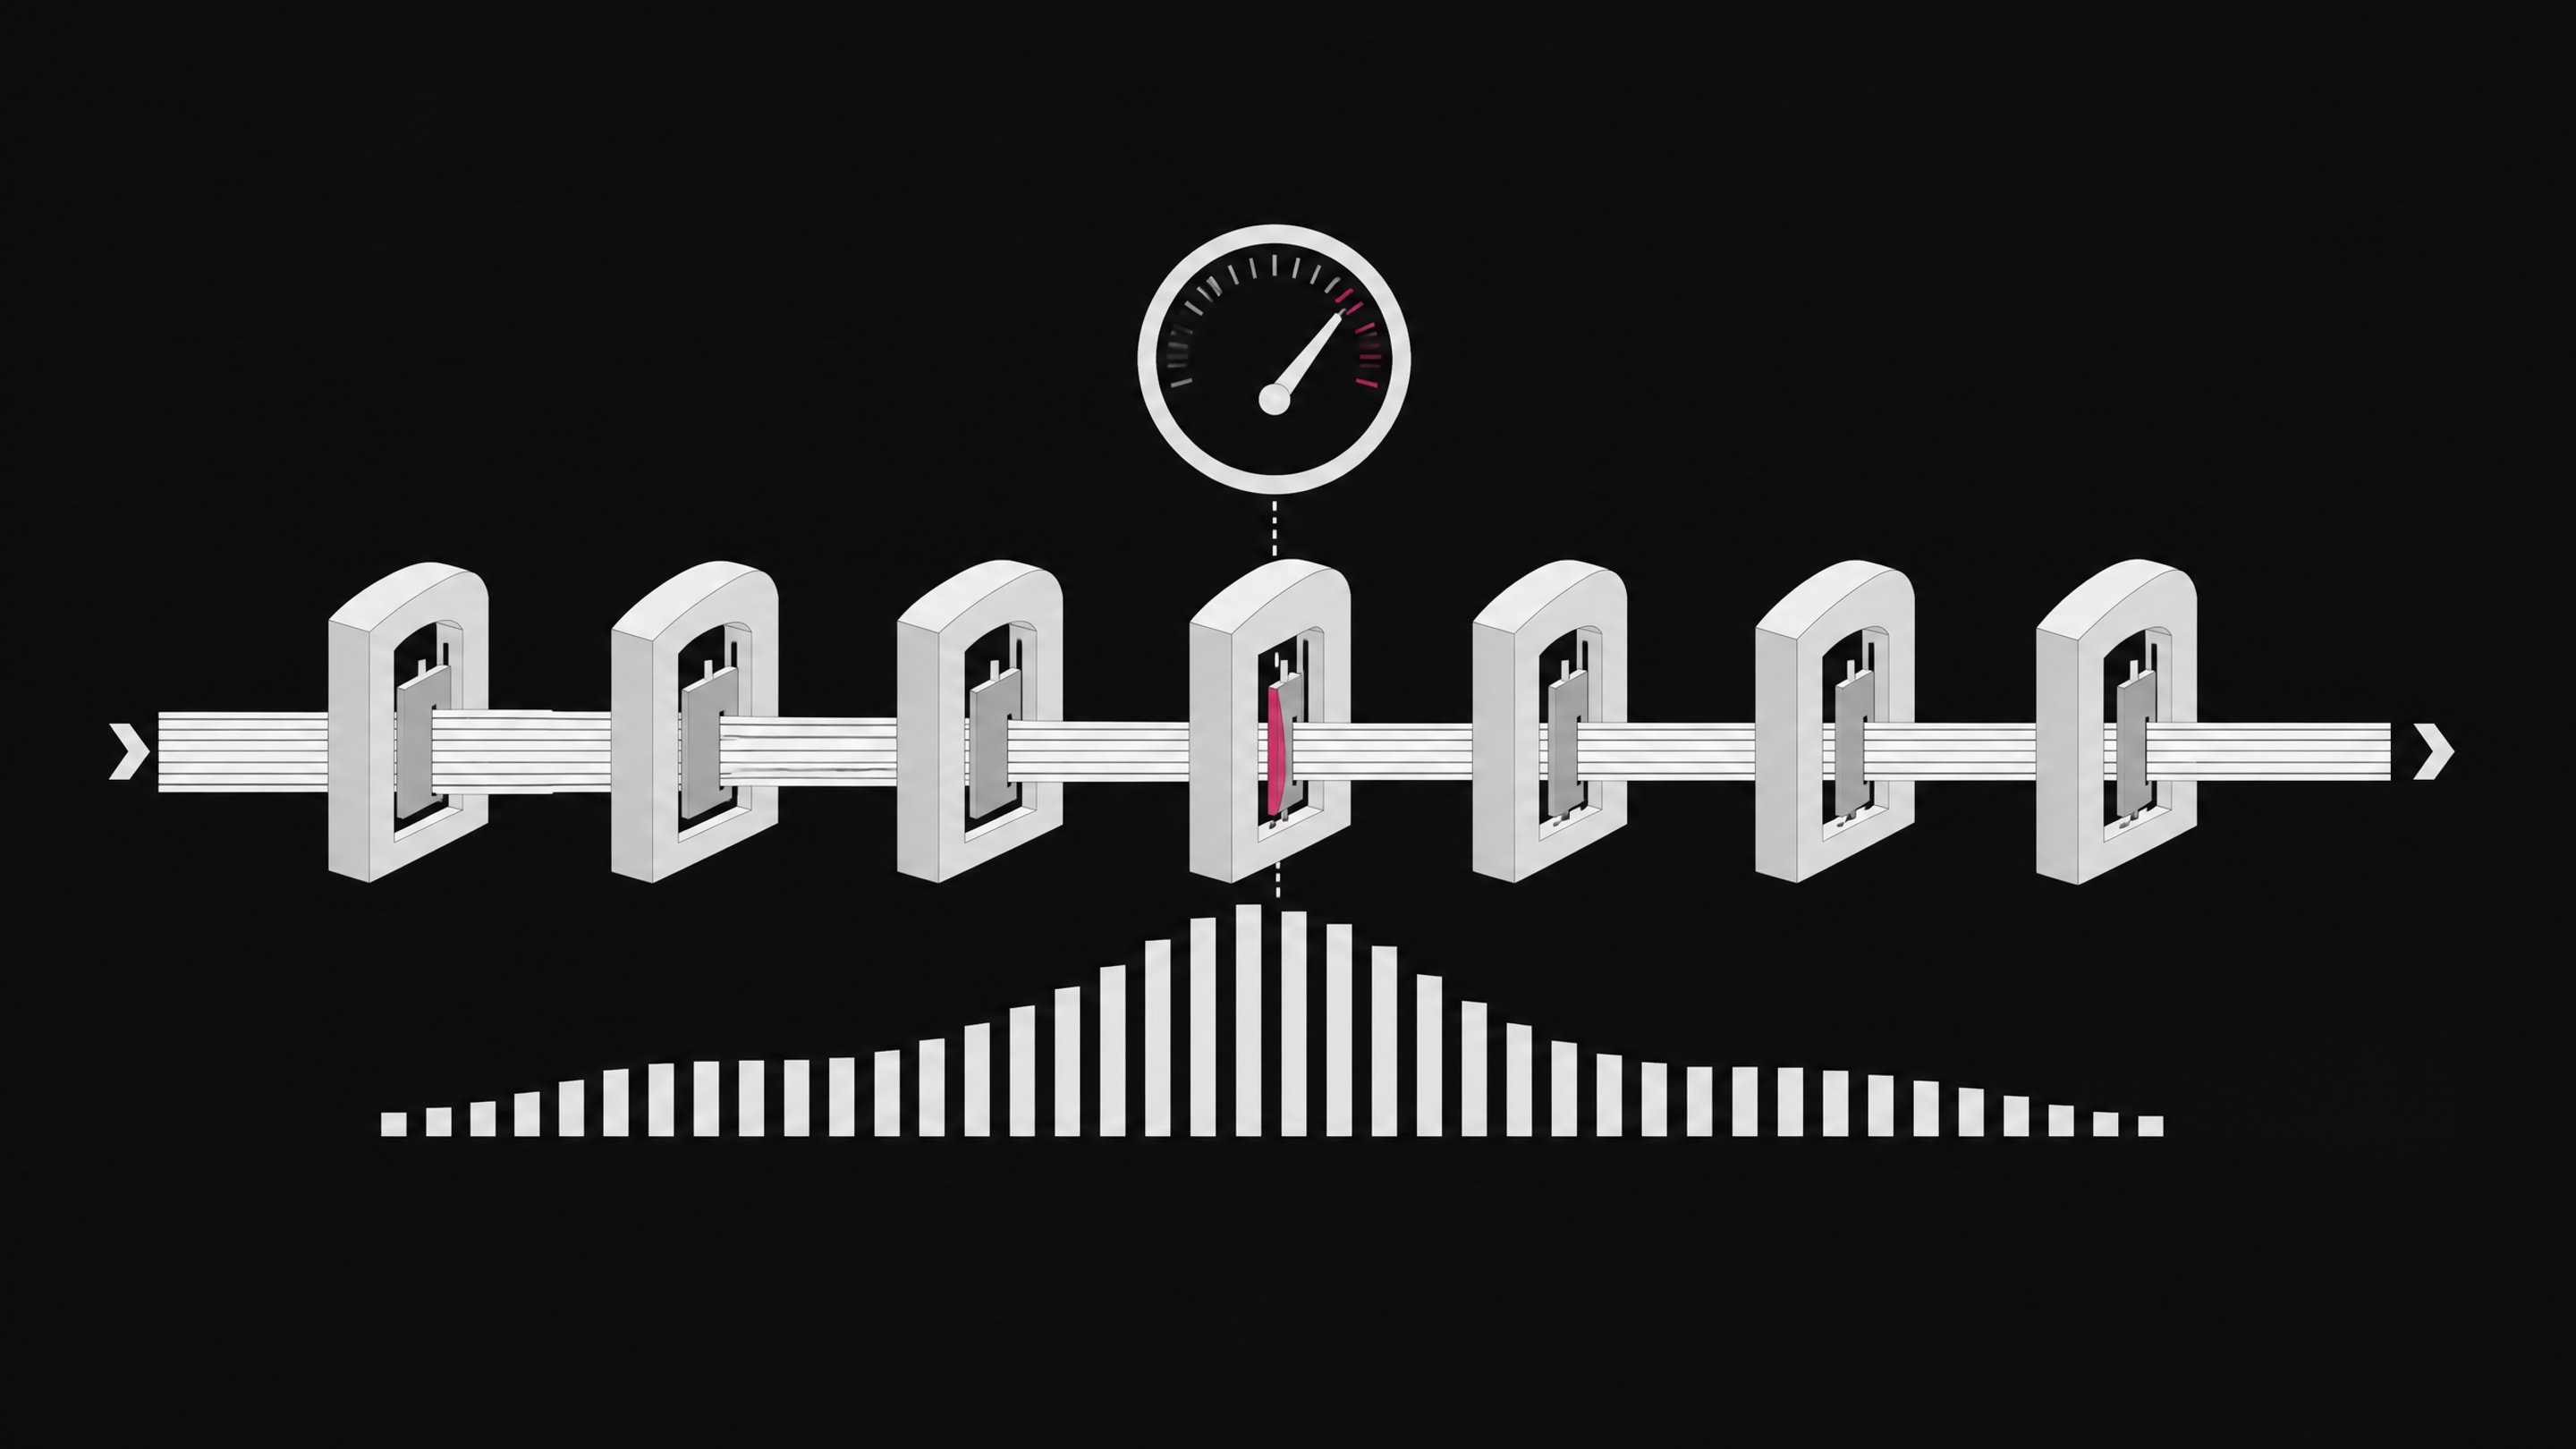
Congestion pricing in API SaaS is a real-time pricing model where the cost of an API call or token rises and falls based on how much demand is competing for the same compute at that moment. Instead of one flat rate, providers sell tiers: pay more and skip the queue, pay less and wait, or eat a premium multiplier during peak load. It's the same logic that prices a toll lane higher at 5 p.m. than at 2 a.m., now applied to GPUs.
If your API bill has swung wildly month to month with no change in your actual usage pattern, this is probably why.
From toll roads to token queues
Congestion pricing isn't new. It's how New York prices its busiest streets and how electricity grids like ERCOT and CAISO price transmission during scarcity. The mechanism is simple: when a shared resource nears capacity, price spikes to ration access, then falls back once capacity frees up. On the grid, this can get extreme. During one documented constraint event, a single node's price swung from 37 cents per megawatt-hour to a $944 surge within five minutes, while the opposite side of the same constraint dropped to negative $660.1
API providers are running the same playbook on compute. GPU capacity is the scarce shared resource. Instead of letting everyone queue first-come, first-served, or eating the cost of over-provisioning for peak load, providers now sell the right to jump the line. Call it what it is: a micro-auction for queue position, priced in tokens instead of dollars per megawatt-hour.
How does congestion pricing show up in API pricing today?
This isn't a theoretical framework. It's already how the biggest model providers price access:
- OpenAI runs four separate service tiers on the same models: Standard, a Fast mode (formerly Priority processing) that costs roughly 1.5 to 2x the standard per-token rate for consistent speed even during peak demand, Flex tier at roughly half the standard price for latency-tolerant workloads, and Scale Tier, where enterprises pre-purchase a fixed token-per-minute allocation for a 30-day minimum term.234
- DeepInfra sells a Priority tier that puts requests at the front of the inference scheduling queue during contention, billed at 1.5x the real-time standard rate, but only charges the premium when priority was actually delivered.5
- xAI's Grok API offers priority processing at a premium per-token rate, with cache discounts still applying before the multiplier kicks in.6
- Azure OpenAI, through Microsoft Foundry, offers the same priority-processing option at the request level, tied to its own published pricing overview.7
Four independent providers, one mechanism. When the shared pool of compute gets tight, price becomes the rationing tool, and customers bid for position with their willingness to pay per token.
Why is congestion pricing happening now?
The conventional wisdom says AI keeps getting cheaper every quarter. True at the unit level, irrelevant at the budget level: unit price and total spend are not the same thing.
Gartner projects that inference on a one-trillion-parameter model will cost AI firms nearly 90% less by 2030 than it did in 2025.8 At the same time, Goldman Sachs forecasts that agentic AI could drive a 24-fold increase in token consumption by 2030, pushing global usage to roughly 120 quadrillion tokens per month.8 Run those two numbers together and the picture is obvious: cost per unit falls, but volume rises so much faster that aggregate bills climb anyway. It's the same dynamic behind the race to the bottom in LLM API pricing, where falling per-token costs haven't translated into cheaper software.
That volume surge is structural, not incidental. L.E.K. Consulting points out that autonomous agents now trigger thousands of API calls for tasks a single person used to complete in one action, which is why more than three-quarters of AI providers admit they still don't know how to price agentic products correctly.9 Congestion pricing is the interim answer: if you can't predict demand shape, price the moments of scarcity directly.
The SaaS budget fallout: when renting becomes a liability
The abstract economics turn concrete fast once real companies hit the wall.
Uber burned through its entire 2026 AI budget by April, four months into the year, after rolling out Anthropic's Claude Code to roughly 5,000 engineers faster than its finance models anticipated. Uber's total 2025 R&D spend was $3.4 billion, and the company's CTO said they were back to the drawing board on cost assumptions.10 Microsoft, facing its own usage spike, canceled most of its direct Claude Code licenses and pushed engineers toward GitHub Copilot CLI just six months after opening access.11
These aren't edge cases. FinOps Foundation survey data shows 73% of AI projects still exceed their allocated budget even after finance teams start actively tracking spend.12 And tracking has become universal: 98% of organizations now actively manage AI spend, up from just 31% two years earlier, with "FinOps for AI" now the top forward-looking priority for the FinOps community.13 Visibility went from rare to standard in two years. Predictability didn't follow it.
Layer the underlying GPU market volatility on top of the API-layer premiums and the risk compounds. Spot pricing on GPU capacity fluctuates with regional demand, and a surge during a critical workload can double or triple expected compute cost before you even factor in a priority-tier multiplier.14 That stacking effect is exactly why finance teams are losing the ability to forecast AI spend a quarter out, let alone a year, and it's part of the broader pattern of cloud cost overruns pushing teams back toward self-hosting.
The economic logic: auctions serve the seller, not your budget
Be honest about who this serves. Auction pricing (English, Dutch, second-price, or the VCG mechanisms borrowed from programmatic ad markets) is explicitly framed in the SaaS pricing literature as a way to allocate scarce compute to whoever values it most at that moment, which in practice means whoever pays the most.15 Snowflake has already experimented with this for computational resources during peak demand.15
That's a rational move for a provider sitting on a fixed pool of GPUs. It captures peak willingness-to-pay instead of leaving revenue on the table during a demand spike. But it's structurally opposed to what a buyer wants, which is a bill that looks roughly the same in March as it did in January. Congestion pricing isn't a bug on someone's pricing page. It's the intended outcome of a system built to maximize seller revenue under scarcity.
Should you build or buy under congestion pricing?
This is where the ownership case gets concrete rather than ideological. Congestion pricing converts a shared, contended resource into a volatile cost. Owned infrastructure, whether that's self-hosted open-weight models, reserved GPU capacity, or in-house request routing, converts that same workload into a fixed, depreciable cost you control.
The math isn't a blanket argument for self-hosting everything. Analysis of enterprise workloads in 2026 puts the break-even point against frontier-model APIs at roughly 100 to 256 million tokens per month, meaning for most teams below that threshold, managed APIs, congestion pricing and all, are still cheaper once you account for the full engineering and operations cost of running your own stack.16 Below that line, buy. Above it, and especially if your usage is spiky enough to keep triggering priority-tier premiums, owning starts to win not just on unit cost but on the thing congestion pricing takes away: predictability. That's the same crossover math laid out in what self-hosting actually costs against API rental, and it's worth running before committing to either extreme.
| Token Volume Fit | Cost Predictability | Exposure to Congestion Pricing | Upfront Investment | Operational Burden | |
|---|---|---|---|---|---|
| Managed API (Buy)Teams under roughly 100-256M tokens/month | Best below ~100-256M tokens/month | Low | High | Low | Low |
| Self-Hosted / Owned Infrastructure (Build)Teams above roughly 100-256M tokens/month with spiky usage | Best above ~100-256M tokens/month | High | Low | High | High |
OpenAI's own Scale Tier is a tell here. It lets enterprises pre-purchase a fixed token-per-minute allocation for a 30-day term at a fixed daily rate, trading pay-as-you-go variability for something that looks a lot like owning a slice of capacity.2 Even the vendors selling congestion pricing are quietly selling its opposite to the customers who can afford to commit.
What SaaS buyers and builders should do now
Most teams don't need to pick a side immediately. They need to stop flying blind. A few concrete moves:
- Tag spend at the gateway, not the invoice. Set budget ceilings by team, project, and model tier before usage happens, not after the bill arrives. This is the FinOps Foundation's core recommendation for managing AI spend, and it's the difference between the 98% who now track spend and the 73% who still blow their budget anyway.1213
- Match workloads to the right tier deliberately. Not every job needs Fast mode or Priority. Batch jobs and non-latency-sensitive workloads belong on Flex or Standard tiers; reserve premium queue position for the handful of workloads where latency actually costs you money.34
- Run the break-even math before you scale an agentic workflow, not after. If a workflow is going to push you past the 100 to 256 million token-per-month range, price out reserved capacity or self-hosting before it becomes an emergency budget conversation like Uber's.1016
- Treat internal tooling as an asset, not a subscription. Teams building their own agents and internal tools with platforms like Remy are effectively opting out of the auction altogether for the parts of their stack where predictable cost matters more than marginal speed.
Congestion pricing isn't going away. It's the rational response to a resource that's scarce and getting scarcer relative to demand, even as unit costs fall. The teams that come out ahead won't be the ones who avoid it entirely. They'll be the ones who know exactly which workloads belong in the auction and which ones belong on infrastructure they actually own.
It's a demand-responsive pricing model where the cost of API calls or tokens rises during periods of high demand and falls when demand eases, often expressed as priority tiers or surge multipliers rather than a single flat price.
OpenAI (Standard, Fast/Priority, Flex, and Scale tiers), DeepInfra (a 1.5x Priority tier), xAI's Grok API, and Azure OpenAI's Foundry Models all offer premium-priced priority processing tied to real-time demand.
Token consumption is growing far faster than unit prices are dropping. Gartner projects inference costs falling nearly 90% by 2030, but Goldman Sachs forecasts a 24-fold rise in token consumption over the same period, so total spend climbs even as the per-token rate shrinks.
Current analysis puts the break-even point against frontier-model APIs at roughly 100 to 256 million tokens per month. Below that, managed APIs are usually cheaper once you factor in the full operating cost of running your own infrastructure.
Set spend ceilings at the API gateway before usage happens, match workloads to the cheapest tier that meets their latency needs, and run break-even math on reserved capacity or self-hosting before scaling any workload that's likely to hit sustained peak-demand pricing.
- 1What Is Grid Congestion, and How Does It Impact Prices?Yes Energy
- 2Scale Tier for API CustomersOpenAI
- 3Fast mode for API CustomersOpenAI
- 4Navigating OpenAI's Pricing Tiers: A FinOps PerspectiveFinout
- 5Introducing the Priority Service Tier: Front-of-Queue Inference When It CountsDeepInfra
- 6Priority Processing | SpaceXAI Docs - Grok API DocumentationxAI
- 7Enable priority processing for Microsoft Foundry ModelsMicrosoft Learn
- 8Microsoft reports are exposing AI's real cost problem: Using the tech is more expensive than paying human employeesFortune
- 9From Seats to Calls: Why API Monetization Is the Next Pricing Frontier in the AI AgeL.E.K. Consulting
- 10Uber Burns Its 2026 AI Budget In Four Months On Claude CodeForbes
- 11Uber burned through its entire 2026 AI budget in four months. Now its COO is questioning whether it's worth itFortune
- 12FinOps Shifts to AI: 98% Track Spend, 73% Blow Budget [2026]Shattered.io
- 13State of FinOps Survey: AI Value and Skills Top Priorities as FinOps Matures Across Technology ValueThe Linux Foundation / FinOps Foundation
- 14What Drives GPU Cloud Cost Volatility and How to Manage ItOneSource Cloud
- 15Auction-Based SaaS Pricing: The Next Frontier in Revenue OptimizationMonetizely
- 16Self-Hosted LLM vs API: The Real Cost and Security Trade-offs for Enterprise in 2026Marka Software