LongCat 2.5 vs Claude Opus 5: Benchmarks and Real Tests
LongCat 2.5 edges Claude Opus 5 on BrowseComp and 3D code generation but trails on Terminal Bench. Here is how it did in a doner kebab and 83-language test.

For Engineering and Executives
How good is LongCat 2.5 compared with Claude Opus 5?
On the vendor's own benchmark table, LongCat 2.5 is mixed against Claude Opus 5. It scores slightly ahead on BrowseComp (a web-browsing research test) and on 3D code generation, and clearly behind on Terminal Bench and Program Bench. In two hands-on tests by a reviewer, a doner kebab web simulation and an 83-language party-name task, the results were weaker than the polished demos suggest. It is a promising open model, but the evidence so far is thin.
TL;DR
- LongCat 2.5 is a 1.6 trillion parameter mixture-of-experts model from Meituan, with about 48 billion parameters active for each token, built for long agentic coding work.
- The biggest story in the vendor's table is the jump from LongCat 2: several agent and coding scores went from very low to competitive.
- Against Claude Opus 5, the table is mixed. LongCat is slightly ahead on BrowseComp and 3D code generation, and clearly behind on Terminal Bench and Program Bench.
- The team says scores without a star were measured in-house and are only indicative, so treat the table as a starting point.
- In one run, the doner kebab simulation did not look like a doner kebab, and the 83-language task produced mostly literal translations instead of culturally grounded names.
- The design on paper is thoughtful and the license is MIT, but access is limited, so most people cannot easily test it themselves.
What is LongCat 2.5?
LongCat 2.5 is a large language model from Meituan, a Chinese company that started in 2010 as a group-buying site (similar to Groupon) and grew into one of China's biggest food delivery and local services platforms. The name Meituan is often rendered as "beautiful group" in English.
Technically, the model is a mixture of experts (MoE). That means the model is made of many specialist sub-networks, and only a few of them activate for each piece of text it processes. LongCat 2.5 has 1.6 trillion parameters in total, but only about 48 billion are active per token. That is why a model this large can still be practical to run, at least in theory.
It accepts both text and images as input. Meituan built it mainly for long agentic work, meaning tasks where the AI plans and takes many steps on its own, such as coding inside a large code base or building a whole project.
What does the LongCat 2.5 benchmark table show?
The vendor's table tells three separate stories.
| Comparison | What the table shows |
|---|---|
| LongCat 2.5 vs LongCat 2 | Several agent and coding tests jump from very low scores to competitive ones |
| LongCat 2.5 vs Claude Opus 5, ahead | BrowseComp and 3D code generation, slightly ahead |
| LongCat 2.5 vs Claude Opus 5, behind | Terminal Bench and Program Bench, clearly behind |
A quick guide to those names:
- BrowseComp tests whether a model can find hard-to-locate information by browsing the web.
- Terminal Bench tests whether a model can complete tasks working in a command-line terminal, the kind of work developers do for setup, debugging and automation.
- Program Bench and 3D code generation test building software, including code that produces 3D scenes.
The generation-over-generation jump is the most solid takeaway. A model that was far off the pace on agent and coding tests is now in the conversation. Against the top closed model, the honest summary is "competitive in places, behind in others."
One caveat matters a lot. The team says scores without a star were measured in-house and are only indicative. Vendor-run comparisons use the vendor's own setup, prompts and settings, and small differences ("slightly ahead") can vanish under different conditions. A table like this is a reason to test, not a verdict.
How did LongCat 2.5 do on the doner kebab test?
The vendor's technical blog shows eight curated demos, all described as generated end-to-end by the model. They cover areas such as professional office work, feedback analysis, a real-time fluid simulation, a 3D exhibition and a city diorama.
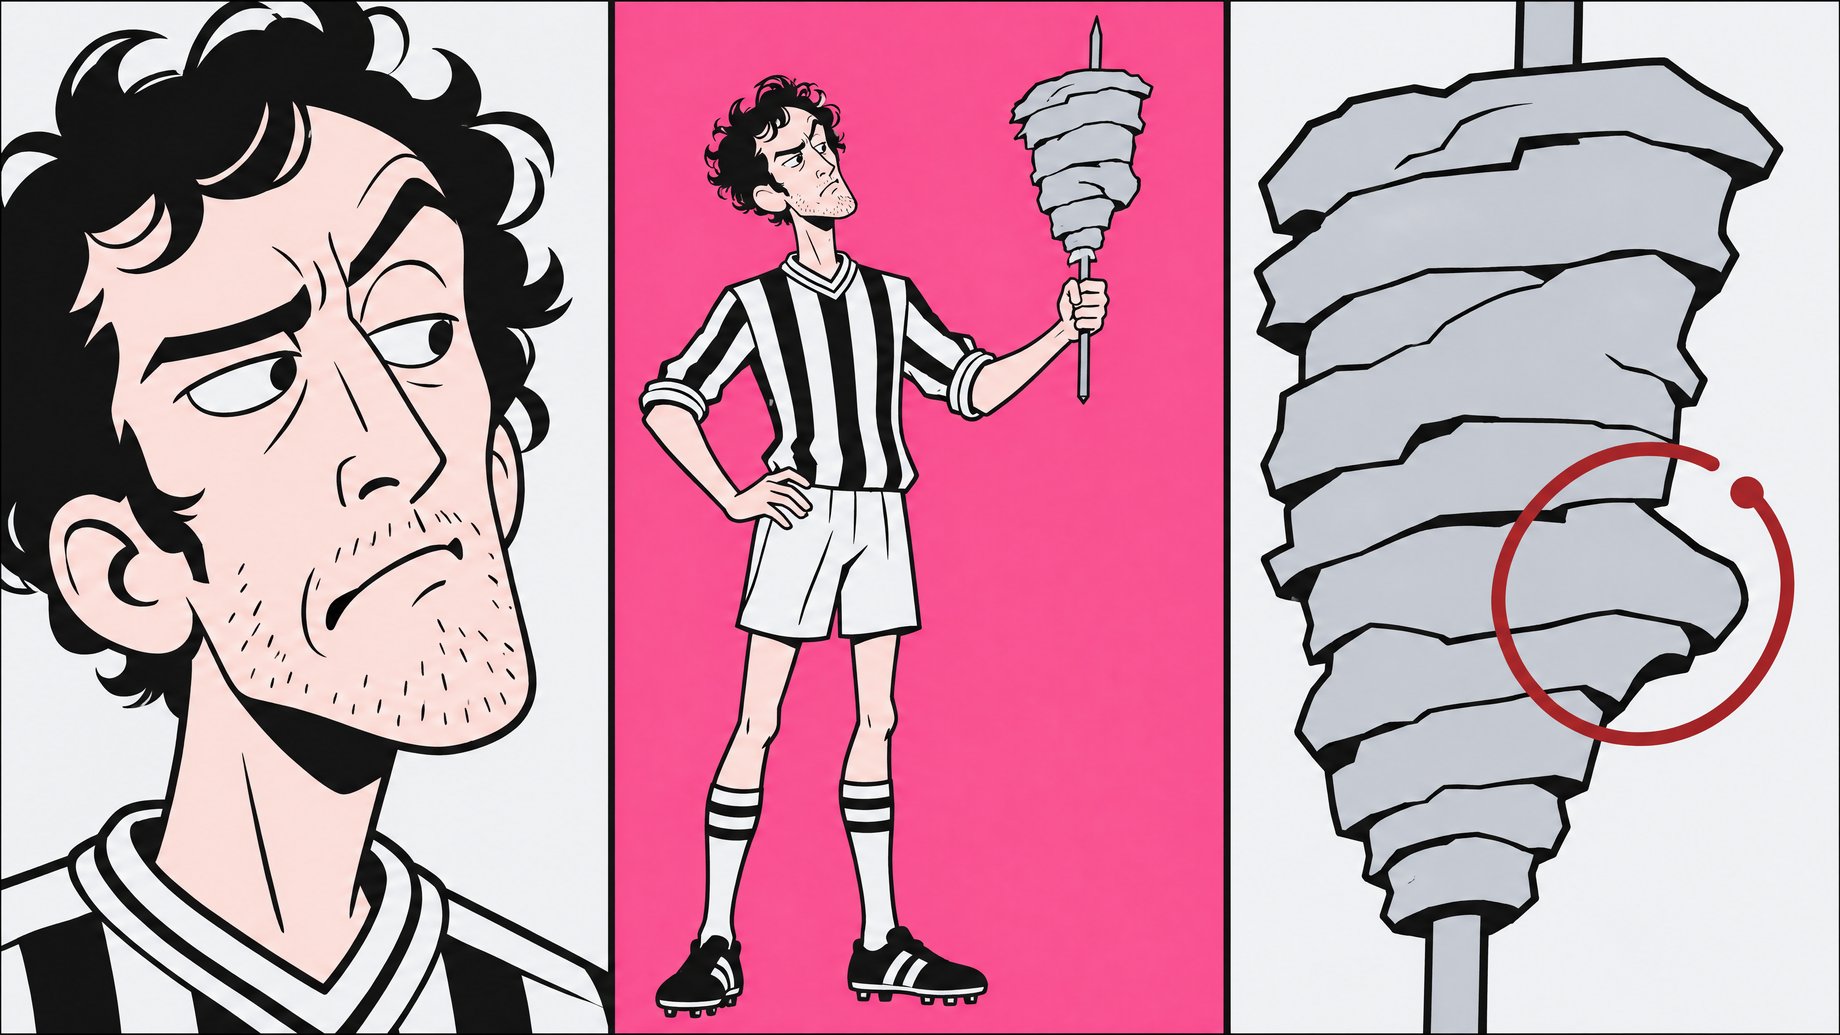
A reviewer tried something similar. He gave the model a photo of a doner kebab and asked it to simulate it in a single web page. The result: a brown, leaf-shaped piece of meat on a metal pole, a grill block at the bottom, a strange gray cut-off shape on the right, and an odd label at the bottom. It did not look like a doner kebab, and it was not the simulation he was after.
Fair caveats apply. This was one run, and it took a long time. One run is an anecdote, not a measurement. Still, the gap between a curated showcase and a first attempt on a fresh prompt is exactly what readers should expect to see with any model. Vendors pick their best outputs. Your first prompt is not their best output.
How did LongCat 2.5 do on the 83-language party-name test?
The second test used the model through OpenCode (a coding tool that can connect to different models). The prompt asked for a name for a new political party with a unique stance on every issue. The reviewer wanted one name in each of 83 languages, from English to Hausa to Latin to Gibberish. The rules: every name should be different from the others and, where possible, grounded in that culture.
What worked:
- It covered every language on the list.
- It used the right script for each.
What did not:
- Almost every name was a translation of the idea "unique party" instead of a fresh, culturally grounded name.
- Names were not really different from one another. Some were very close, such as Hindi and Bhojpuri, or other regional languages.
- In the Nepali line, the model left its own correction notes in the answer.
- The Saraiki entry was simply another translation of "unique."
The reviewer could not check every language himself and asked native speakers to weigh in, which is a fair limit to keep in mind. But the pattern is clear. The model followed the instruction to produce 83 outputs, and missed the harder instruction to make each one distinct and culturally rooted. That kind of gap, between completing the format and doing the spirit of the task, is common in AI models and easy to miss in a benchmark table.
Is the design behind LongCat 2.5 any good?
On paper, yes. The technical blog is described as a solid document, and two design choices stand out.
Images at any size. Four very different images (a newspaper front page, a line of handwritten math, a small photo of toy figures, a hamster close-up) each keep their own width and height. The model does not shrink or crop them to one fixed size. A vision tokenizer turns each image into a list of discrete IDs, and a bigger image simply gets a longer list. A de-tokenizer can rebuild the image from those tokens. The goal is for pictures and text to become the same kind of tokens inside one model. The team also says image tokens are computed ahead of time and cached, which simplifies training.
Training on real software tasks. For agentic coding, each training step works like this:
- Take real GitHub pull requests and issues, build a working environment for each, and check it with tests. One test should fail before the fix and pass after. Another should keep passing.
- Let the model attempt the task inside a locked-down sandbox with no web search.
- Reward it based on the tests, plus an LLM judge that looks for cheating. Penalties apply for repeated reasoning and for answers that grow too long.
Both ideas make sense for a coding agent. The license is MIT, which is permissive and a plus for anyone who wants to build on the model. But a good design is a plan, not a result. What matters is how the model behaves on your work.
Why is LongCat 2.5 hard to try?
This is a practical problem the reviewer called out. Running a 1.6 trillion parameter model locally is hard because of its size. API access from providers is also limited. He noted that free access was on offer through OpenCode, but even with a paid account he could not get it to run more than two prompts before giving up.
If you cannot easily run a model, you cannot easily check a vendor's claims. The reviewer's suggestion to Meituan was to provide a proper hosted chat window or a straightforward API so people can test it. Until then, most claims about LongCat 2.5 come from the vendor's table and a handful of reviewer runs.
What does this mean for you?
If you use AI at work but do not pick models: nothing changes today. LongCat 2.5 is a model to watch, not one to switch to. Your current tools are fine.
If you help choose AI tools for a team: treat vendor tables as a shortlist filter. A "slightly ahead" on one benchmark and "clearly behind" on another tells you the model has a profile, not a rank. Match the profile to your work. Web research-heavy tasks look at BrowseComp. Terminal-heavy engineering work looks at Terminal Bench.
If you can run your own tests: build a small test set from real tasks, not demos. Use 5 to 10 prompts from your actual work, run each model on all of them, and score the outputs the same way. Include at least one task where the instruction has a hard, easy-to-miss part, like the "make every name different and culturally grounded" requirement above. Run important prompts more than once, since one run can mislead in either direction.
Prompt template for a quick comparison:
Task: [paste a real task from your work]
Constraints: [2 or 3 specific rules the answer must follow]
Check: after answering, list each constraint and say whether you met it.
Then check the constraints yourself. Do not rely on the model's self-report.
How could you run model tests without a pile of spreadsheets?
Comparing models on your own tasks means tracking prompts, outputs, scores and notes across several tools. A small internal app can hold that: a form to add a test prompt, a table to record each model's output, and a score column your team fills in. You could describe that tracker in plain English to Remy, which builds and deploys full-stack apps from a description. Remy's catalog includes nearly 400 AI models with no API keys to manage, so the same app could run prompts against several models, though you would need to check whether a specific model such as LongCat 2.5 is listed.
Frequently Asked Questions
Is LongCat 2.5 better than Claude Opus 5?
Not across the board, based on the vendor's own table. It is slightly ahead on BrowseComp and 3D code generation, and clearly behind on Terminal Bench and Program Bench. The team also says unstarred scores were measured in-house and are only indicative.
How big is LongCat 2.5?
It is a mixture-of-experts model with 1.6 trillion parameters in total, about 48 billion of which are active for each token. It accepts text and images as input and is aimed at long agentic work such as coding in large code bases.
Is LongCat 2.5 open source?
The license is MIT, which is permissive. The reviewer noted that the paper explains the design in real detail. Running it yourself is another matter, since its size makes local installation hard and hosted access has been limited.
Why did the doner kebab test fail?
The source does not say why. In one run, the model produced a page that did not resemble a doner kebab, with an odd shape and label. One run is not enough to draw a firm conclusion, but it shows a gap from the curated demos.
How should I evaluate a new AI model?
Skip the demos and benchmark tables as final answers. Build a small set of real tasks from your own work, include instructions with hard parts, run each model the same way, and score the results yourself.
Useful for
How we source, write, and correct our articles. Editorial standards
Related articles
Maxwell V1 Flash Review: Coding, Languages and Research Tests

Live Nerf vs Margin Lab: Do AI Models Really Get Worse?
Why Is Nvidia So Dominant in AI Chips? The CUDA Moat Explained