How Are LLMs Trained? Neural Networks and Backpropagation
How do neural networks and LLMs learn? A plain-English walkthrough of weights, loss, backpropagation and learning rate, using an apartment price example.

For Engineering and Data & Analytics
How are LLMs trained?
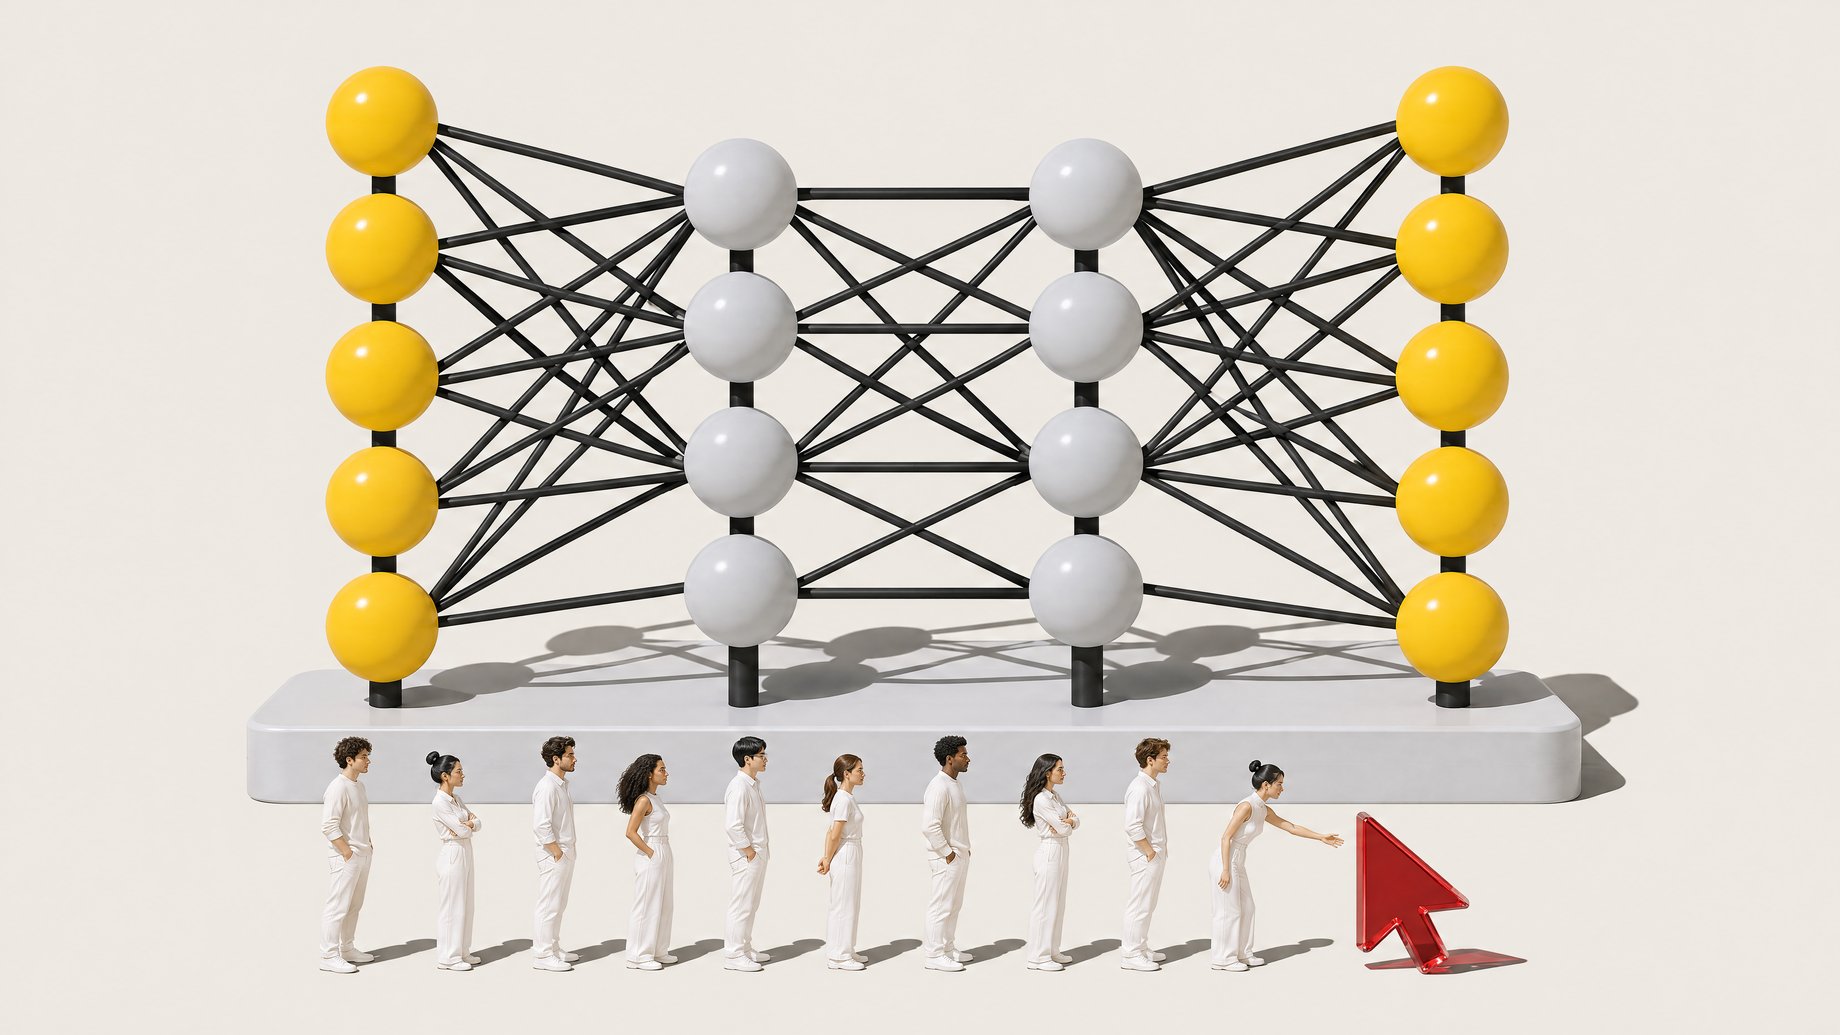
A large language model learns by making a guess, measuring how wrong the guess was, and nudging millions or billions of internal numbers so the next guess is a little less wrong. Then it repeats this loop an enormous number of times. Those internal numbers are called parameters (or weights). The "brain" of a model is nothing more than a file of them, plus a short program that describes how they are wired together. The rest of this article builds that idea up from a simple example.
TL;DR
- A neural network is a function with adjustable knobs. Training means turning those knobs until the function's answers match real data.
- The knobs are called parameters or weights. A "2 trillion parameter model" is a model with 2 trillion of these numbers.
- Loss is a single number that says how far off the model's predictions are. Training tries to push it down.
- Backpropagation is how the computer figures out which direction to turn every knob, automatically, instead of a human tuning them by hand.
- The learning rate controls how big each nudge is. Too big overshoots, too small takes forever.
- A finished model is a file of numbers plus a small Python program, which is why open models can be downloaded and run.
What is a neural network, in plain terms?
Start with a problem a real estate broker handles every day: pricing apartments. Imagine a sheet of New York apartments. Each row has inputs (the neighborhood, say SoHo, the square footage, the number of bathrooms) and the price the apartment actually sold for.
Your goal is to find the pattern, the function, that turns those inputs into a price.
The old way is to write the rules yourself. If the square footage is between 1,000 and 2,000 and there are one or two baths, price it around here. That works with seven rows. It falls apart with millions of rows, or when you have hundreds of inputs instead of three (finishes, year built, floor, and so on). A broker holds a fuzzy version of all this in their head. Nobody can hand-code it.
A neural network flips the approach. Instead of you writing the function, the computer builds it from the data.
What are the "knobs" in a neural network?
Take the apartment example and make it as simple as possible. Convert each input to a number. Multiply each one by a knob, which is just a number. Add the results. That total is your predicted price.
In the toy version, you might start with random settings: 0.25 on size, 0.05 on bathrooms, 0.15 on location. The first predictions come out wrong, because the knobs were set randomly. But there is some combination of knob settings that gets you close to the real prices.
Each knob works like an importance setting. A high value on square footage says size matters a lot to the price. A low value on location says it matters less. Training is the search for good settings.
Real networks do not stop at one step. The output of one set of knobs becomes the input to another set, and then another. That is a function inside a function inside a function, and each stage is called a layer. More knobs and more layers let the network represent much more complicated patterns than a single weighted sum can. If three knobs can't fit the data, you add more.
What is loss?
You need a way to score the model. That score is loss: the gap between what the model predicted and what actually happened.
If an apartment in SoHo sold for $2 million and the model says $1 million, that is a big miss. Average the misses across all your example apartments and you get one number: on average, the model's predictions are off by this much. In the toy example, that number was around $0.2 million at one point.
Training has one goal: make that number smaller.
How does backpropagation work?
You could lower the loss by hand. Turn a knob, rerun every example, see if the loss went up or down, repeat. With three knobs that is tedious. With billions, it is impossible.
The key invention is letting the computer work out the adjustment for every knob automatically. Here is the logic, without the calculus.
- Run the inputs through the network and get predictions.
- Compute the loss.
- Ask, for each knob: if I nudged this one slightly, how much would the loss change? Say that raising the size weight by 1 would raise the loss by 3.
- Move each knob the opposite way. If raising the size weight makes things worse, lower it a bit. The loss drops.
Doing step 3 for every parameter at once is what backpropagation does. It works backward from the loss through the layers, which is where the name comes from. The math behind it is the derivative: the rate at which the loss changes as one parameter changes.
Software called an autograd engine handles this bookkeeping. PyTorch is the widely used example, and JAX and TensorFlow do the same job. While your data flows forward through the network, the engine records every number and every calculation involved. When the loss comes out, it can trace back and report each parameter's effect on it. Engineers do not derive these by hand. They write the forward function, and the engine supplies the knob-by-knob adjustments.
What does the learning rate do?
Knowing which direction to turn a knob does not tell you how far. That is the job of the learning rate, a setting chosen by the people running the training.
Back to the example where raising the size weight by 1 raises the loss by 3. The slope only holds near the current setting. If you take a huge step in the opposite direction, you can overshoot the best value and land somewhere worse. If you take tiny steps, the model improves, but so slowly that training takes impractically long.
So the standard practice is to take small steps, recheck, and step again. A training run is that cycle repeated many times: predict, measure loss, work out each knob's effect, nudge every knob a little. Choosing the learning rate well is one of the practical skills of training models.
Is a language model really just a file of numbers?
Yes, and it is worth sitting with that. A trained neural network is two things:
| Piece | What it is | Role |
|---|---|---|
| Parameters | A file of numbers | The learned "brain" |
| Wiring code | A relatively small Python program | Describes how the numbers connect and in what order |
Downloading an open model from a hub like Hugging Face means downloading the numbers. When someone says a model has 2 trillion parameters, they mean 2 trillion of these knob settings. Running the model means pushing your input through that wiring, multiplying and adding along the way, and reading out the result.
Language models use the same machinery as the apartment example, at far larger scale. Instead of square footage and bathrooms, the inputs are text converted into numbers. Instead of predicting a price, a basic language model predicts what comes next in the text. Loss measures how wrong that prediction was. The knobs get nudged the same way. The apartment sheet becomes a vast body of text, and the one-layer toy function becomes a very deep stack of layers.
The researcher who walked through this idea, an Anthropic researcher, framed the point the same way: intelligent systems start from a file of numbers and a small program. Later stages such as pre-training, post-training and reinforcement learning build on this same foundation, and this article covers only the foundation.
What does this mean for you?
You do not need to train a model to benefit from understanding how it was trained. Three practical takeaways:
- Models reflect their data. A model fits patterns in what it was trained on. If your question is far from that data, expect weaker answers. This is why checking outputs matters, especially for numbers, names and facts.
- Wrong answers are not lies. The model produces what minimized loss during training, not what it verified. Treat confident phrasing with the same caution as a confident guess.
- "Training" and "using" are different jobs. Training adjusts the parameters, and it costs a lot. Using a model runs your input through parameters that are already fixed. Almost everyone at work is in the second group, and that is fine.
If you manage a team that is evaluating AI tools, one useful question for a vendor is whether they trained their own model or are building on an existing one. Both are legitimate. The answer tells you where the real work and cost sit.
If you want to go deeper, try recreating the apartment example yourself. A few lines in PyTorch can fit a handful of made-up apartments. Watching the loss fall as the knobs adjust makes the idea concrete faster than reading about it.
Do you need to train a model to build something useful with AI?
No. Most workplace tools use models someone else already trained, and the useful work is deciding what the tool should do. If the apartment example sparked an idea, say a small internal tool that collects listings, runs them through an AI model and tracks asking price against your own estimates, you can describe that to Remy in plain English. Remy builds and deploys the full-stack app, with a database, sign-in and access to nearly 400 AI models without managing API keys. It is a way to own a small tracker instead of adding another spreadsheet or subscription.
Frequently Asked Questions
What is a parameter in an LLM?
A parameter is one of the numbers inside the model that gets adjusted during training. It works like a knob that sets how strongly one signal influences the next step. A model described as having 2 trillion parameters has 2 trillion of these numbers.
What is the difference between backpropagation and gradient descent?
Backpropagation is the method for working out how each parameter affects the loss. Gradient descent is the step that uses that information to nudge the parameters in the direction that lowers the loss. They work together in every training loop.
Why is it called a "neural" network?
The name comes from a loose inspiration from brain cells that pass signals to one another. In practice, a neural network is arithmetic: numbers multiplied by weights, added up and passed through layers. You do not need any biology to understand how it learns.
What is PyTorch used for?
PyTorch is a software library for building and training neural networks. Its autograd feature tracks every calculation so it can compute how much each parameter affects the loss, which removes the need to work out those adjustments by hand.
Can I run a trained model on my own computer?
Often yes, because a model is a file of parameters plus a small program that describes the wiring. Whether it runs well depends on the model's size and your hardware. Larger models need far more memory than a typical work laptop has.
How we source, write, and correct our articles. Editorial standards
Related articles
How to Run Underdog Woof TTS on a CPU (and Is It Free to Use?)
How Good Is Qwen4 Max? Hands-On Tests vs Qwen 3.8
Underdog Woof TTS Review: How Accurate Is It, Really?